The field that looks right can still poison the workflow.
A total is read correctly but assigned to tax. A date is extracted but parsed in the wrong order. A supplier name is close enough to pass a visual scan and wrong enough to create a duplicate record.
Intelligent document processing turns an image into trusted data only after classification, extraction, validation, and review agree. RaftLabs builds that full path into the operation that consumes the result.
Proof
- 20,000+
- transactions processed in one test day
- Gas-station AI OCR project record
- 40+
- stations connected during beta rollout
- RaftLabs project record
- 16 weeks
- gas-station platform delivery
- RaftLabs project record
IDP fits a repeated document flow with a measurable error boundary.
Start with one document type. A vague promise to process every document hides the layouts and exceptions that decide quality.
A fit01People repeatedly read the same document type and enter defined fields into another system.
02You can provide representative samples, including poor scans and uncommon layouts.
03A process owner can define field-level tolerance, review rules, and the system of record.
Not a fit01The documents are rare, highly bespoke, and require expert interpretation throughout.
02No representative samples can be used for evaluation.
03The downstream process has no stable fields, validation rules, or accountable reviewer.
Scope
What an IDP workflow can cover
01Intake and classification
Accept documents from uploads, email, scanners, storage, or an existing
product. Identify the document type and source before extraction so the
correct field schema and rules apply.
02Field and table extraction
Extract the named values the process needs, including text fields, dates,
totals, parties, line items, and tables. Results retain their source location
and confidence so a reviewer can see what the system read.
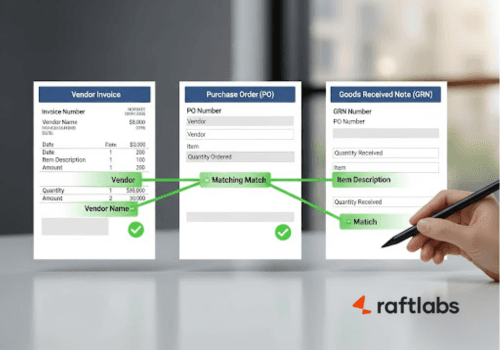
03Validation and matching
Check formats, totals, cross-field relationships, duplicates, and approved
master data. A plausible string does not pass merely because the extraction
model is confident.
04Exception review and delivery
Send failed or uncertain fields to a focused review queue, preserve
corrections, and deliver accepted structured data to the destination through
its supported interface. Reconciliation confirms that the receiving system
accepted the record.
Where OCR stops and IDP begins
| OCR | Intelligent document processing |
|---|
| Primary job | Convert an image of text into characters | Turn a document into validated structured data |
| Document type | Often supplied by the caller or template | Classified before the correct rules run |
| Quality unit | Character or word recognition | Required field accepted at the agreed error boundary |
| Exceptions | Raw confidence or output | A review queue with source, reason, and correction |
| Destination | Text returned to the caller | Accepted data reconciled with a system of record |
OCR may be enough when searchable text is the outcome. IDP earns its place when the next system needs named, checked fields and the operation needs to account for uncertain ones.
Choose OCR development when recognition itself is the deliverable. Choose workflow automation when the documents are already structured and the main problem is routing work between systems.
How it works
How we develop an IDP workflow
The benchmark uses the documents your team actually receives, not a clean demonstration set.
- Phase 1
01Sample the real document mix
Collect representative files across layouts, sources, image quality,
languages, and edge cases. Name every required field and the downstream
consequence of an incorrect or missing value.
- Phase 2
02Benchmark fields and confidence
Compare extraction approaches on held-back samples. Measure each required
field, not one blended accuracy number. Define thresholds for automatic
acceptance, rejection, and human review.
- Phase 3
03Build validation and exception review
Add format and business checks, source lookups, duplicate detection, reviewer
permissions, and correction history. The reviewer sees the document and
flagged field together.
- Phase 4
04Connect and expand carefully
Deliver accepted data to one destination and reconcile its status. Add new
layouts or document types only after the first workflow meets its field-level
benchmark in production.
RaftLabs built a gas-station management platform with AI OCR that connected to existing point-of-sale systems. During testing, it processed more than 20,000 transactions in one day; 40+ stations joined the beta rollout.
That proof belongs to the tested platform and document mix. It is not a universal IDP accuracy or throughput promise. A new workflow begins with its own samples, fields, integrations, and acceptance threshold.
- One accuracy number
- A blended score can hide a weak total, date, or identifier. Measure the fields that create downstream risk separately.
- Clean samples only
- Include rotations, shadows, folds, scans, photos, uncommon layouts, and other conditions the live queue contains.
- Confidence without validation
- A model can be confident and wrong. Business rules, master-data checks, and cross-field checks catch a different class of error.
- No reconciliation
- Posting data is not the same as acceptance. Record destination status and make failed or duplicate delivery visible.
Scope and price
Start with one document type and one destination.
The first scope covers representative samples, named fields, extraction, validation, exception review, and one integration.
More document types, languages, handwriting, tables, throughput, and destination systems belong in later phases after the first benchmark holds.
Starting investment
Starts at $30,000
A focused workflow commonly takes 8 to 14 weeks. Layout variation and field-level error tolerance move the estimate most.
Benchmark before scale
The first phase reports quality by required field on held-back samples. We do
not turn a demo accuracy figure into a production promise.
Fixed-price phase
Once the sample, fields, review path, and destination are agreed, the phase
price is locked in writing.