An accurate model nobody uses is still a failed product.
The data team improves a validation score. Operations still exports a spreadsheet and makes the decision the old way. The prediction arrived, but the workflow did not change.
RaftLabs develops the full path from data to decision. That includes the baseline, model, threshold, integration, monitoring, and fallback a production system needs.
Proof
- less time on routine clinical decisions
- 20%
- Adjacent AI project record, not an ML-model benchmark
- healthcare AI release
- 12 weeks
- Adjacent RaftLabs delivery evidence
- average client rating
- 4.9/5
- Clutch, verified reviews
Machine learning starts with a decision, not a dataset.
The first question is whether historical data can improve a named choice beyond the current baseline.
A fit01A repeated decision would benefit from a forecast, score, ranking, classification, or anomaly signal.
02Historical examples cover the conditions the production system is likely to see.
03The team can define the cost of false positives, false negatives, delay, or forecast error.
Not a fit01The desired output is generated text or images rather than a prediction from historical patterns.
02The process has no stable outcome, label, or proxy that can be evaluated.
03A simple rule or standard analytics report already answers the question well enough.
Scope
What a production ML system can cover
01Forecasting and planning
Predict demand, capacity, workload, revenue, or another time-dependent
measure. The system preserves the forecast horizon, uncertainty, and version
used for each planning decision rather than showing one unexplained number.
02Classification and risk scoring
Assign a class or score to a case, event, customer, or transaction. Thresholds
reflect the cost of different errors, and uncertain or high-impact cases can
move to human review instead of receiving an automatic outcome.
03Ranking and recommendations
Order products, content, leads, tasks, or next steps against a defined
objective. Evaluation checks offline ranking quality and live behaviour, while
product rules preserve availability, eligibility, and other hard constraints.
04Anomaly and pattern detection
Flag unusual behaviour for investigation when fixed rules miss changing
patterns. The workflow explains what changed, suppresses known noise, and
collects reviewer outcomes without presenting an anomaly as proof of fraud or
fault.
Choose the simplest system that improves the decision
| Approach | Best fit |
|---|
| Business rules | Known conditions lead to known outcomes | The logic must be explicit and deterministic |
|---|
| Analytics | People need visibility into past and current performance | A dashboard supports judgment without predicting |
|---|
| Machine learning | Historical patterns can improve a future score or ranking | The decision tolerates measured uncertainty |
|---|
| Generative AI | The system creates or transforms content | Text, image, audio, or structured output is the job |
|---|
A baseline is part of the product decision. If a rule, average, or existing analytics method performs well enough, a custom model adds maintenance without earning its place.
Use predictive analytics when the buyer question begins with a business forecast or score. Use generative AI development when the desired output is content. A dedicated MLOps engagement fits teams that already have models and need deployment or model operations.
How it works
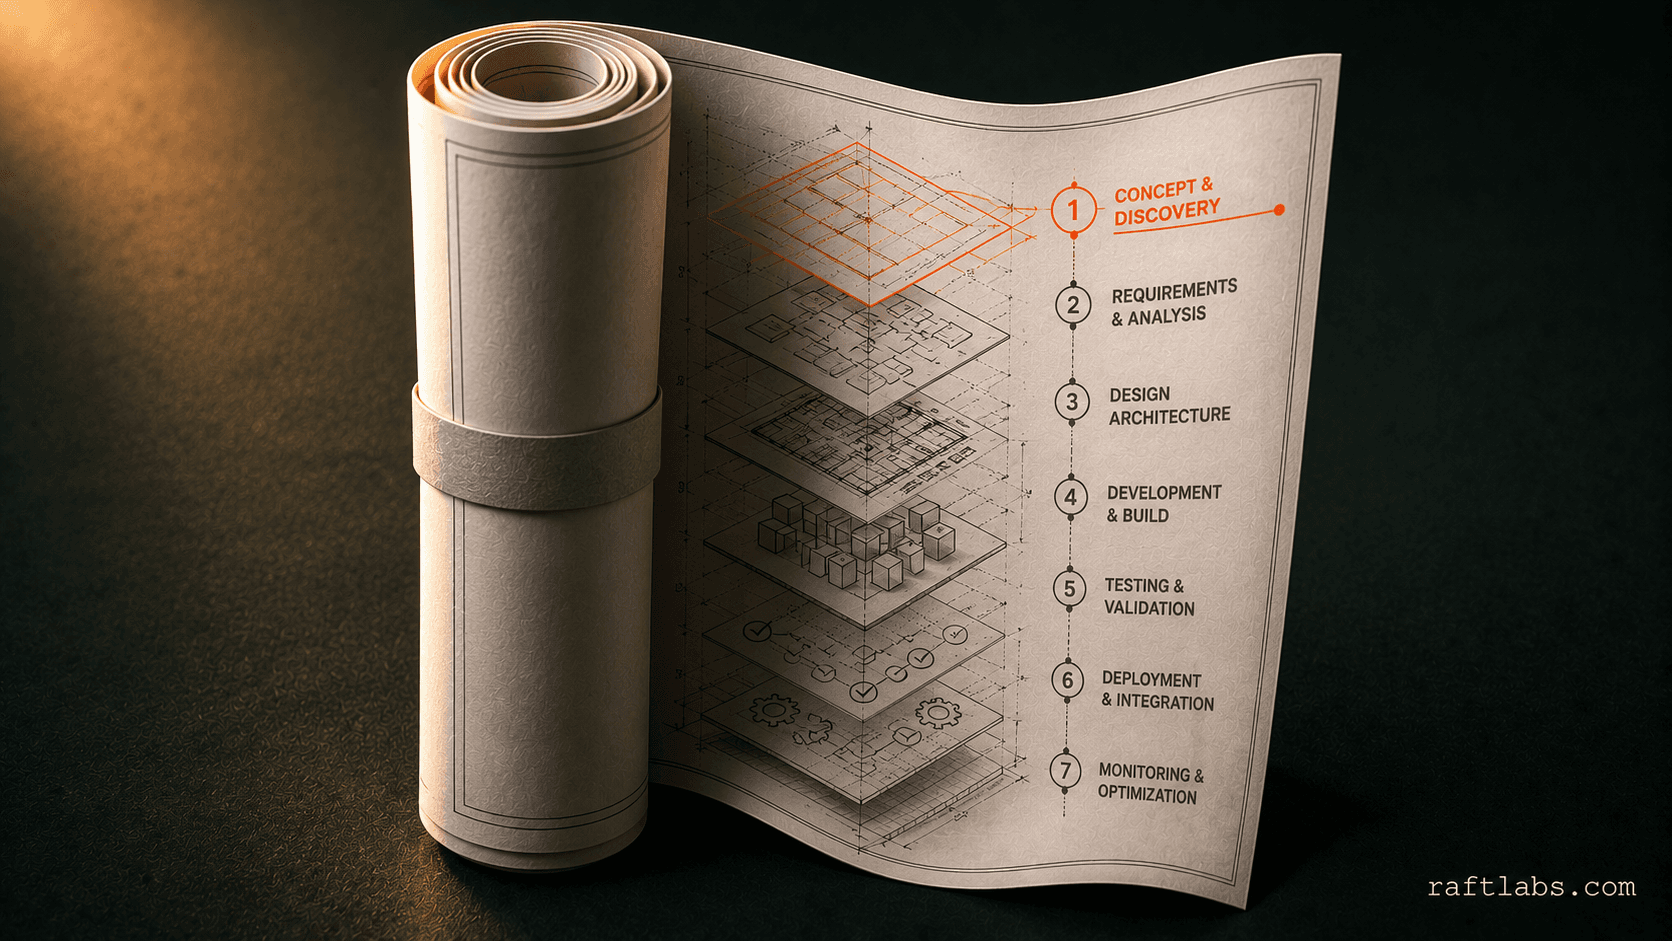
How we move an ML model into production
The model must beat a baseline and reach the person or system that uses the result.
- Phase 1
01Define the prediction and baseline
Name the decision, prediction horizon, current method, and cost of each error.
Agree the evaluation window and threshold that would justify changing the
workflow.
- Phase 2
02Audit data and prove signal
Check labels, missing periods, leakage, class balance, and whether the data
represents current conditions. Compare candidate models with a simple baseline
on held-back data.
- Phase 3
03Connect the model to the decision
Deliver the score, confidence, and relevant explanation into the product,
queue, or planning tool. Add versioning, monitoring, access control, and a
fallback when inference fails.
- Phase 4
04Monitor drift and retraining
Track input change, model performance, and the business outcome the prediction
was meant to improve. Define who approves retraining and what evidence a new
model must pass before release.
- Data leakage
- A training feature quietly includes information that will not exist at prediction time. The validation score looks excellent and production performance collapses.
- The wrong metric
- One aggregate score can hide the error that costs the business most. Select the threshold and measures around the real decision tradeoff.
- No workflow adoption
- A prediction in a separate dashboard asks users to create a new habit. Put the result where the decision already happens and record whether it was used.
- Silent drift
- Customer behaviour, operations, and source systems change. Monitor inputs and outcomes so deterioration becomes a review trigger rather than a surprise.
Scope and price
Start with one prediction and one decision path.
The first production scope covers a bounded data source, baseline, model comparison, delivery into one workflow, and monitoring.
When signal or label quality is unknown, start with a 3 to 6 week feasibility phase and stop if the model cannot beat the agreed baseline.
Starting investment
Starts at $25,000
A focused production system commonly takes 8 to 16 weeks. Data readiness is the largest source of uncertainty.
Baseline before model
We do not call a model successful because it produced a score. It must clear
the metric and threshold agreed for the decision.
Fixed-price phase
Once data access and scope are understood, the phase price and acceptance
criteria are agreed in writing.