"Incredibly simple and easy to use app. Exactly what we were looking for."
Nuala C.
Director, BrandFire
Real-Time Application Development
We build real-time application features for live operations, collaboration, tracking, alerts, and state synchronisation. The work starts by defining freshness, ordering, delivery, reconnection, permissions, scale, and degraded behaviour, then choosing WebSocket, server-sent events, webhooks, queues, or simpler polling. Real-time delivery reduces delay; it does not make upstream data correct.
Bring the problem, the current workflow, or the existing code. We reply with a practical next step within one business day.
The brief
Good software decisions begin with the constraint, not a list of features or a preferred technology.
Users refresh dashboards or wait for scheduled jobs while an operational event is already changing what they should do?
A WebSocket prototype works with a few users but cannot explain ordering, missed events, reconnects, fan-out, backpressure, or recovery?
Plain answer
Real-time application development delivers events to users or systems within an agreed freshness window using WebSocket, server-sent events, webhooks, queues, or streams. RaftLabs defines ordering, delivery, reconnect, recovery, security, and load behaviour before building. A focused workflow starts at $20K and commonly takes 8 to 12 weeks.
What to remember
After reconnect, some users saw a stale snapshot, others received events twice, and nobody knew whether the red status meant a fresh incident or an old message.
Real-time engineering is mostly about what happens between updates.
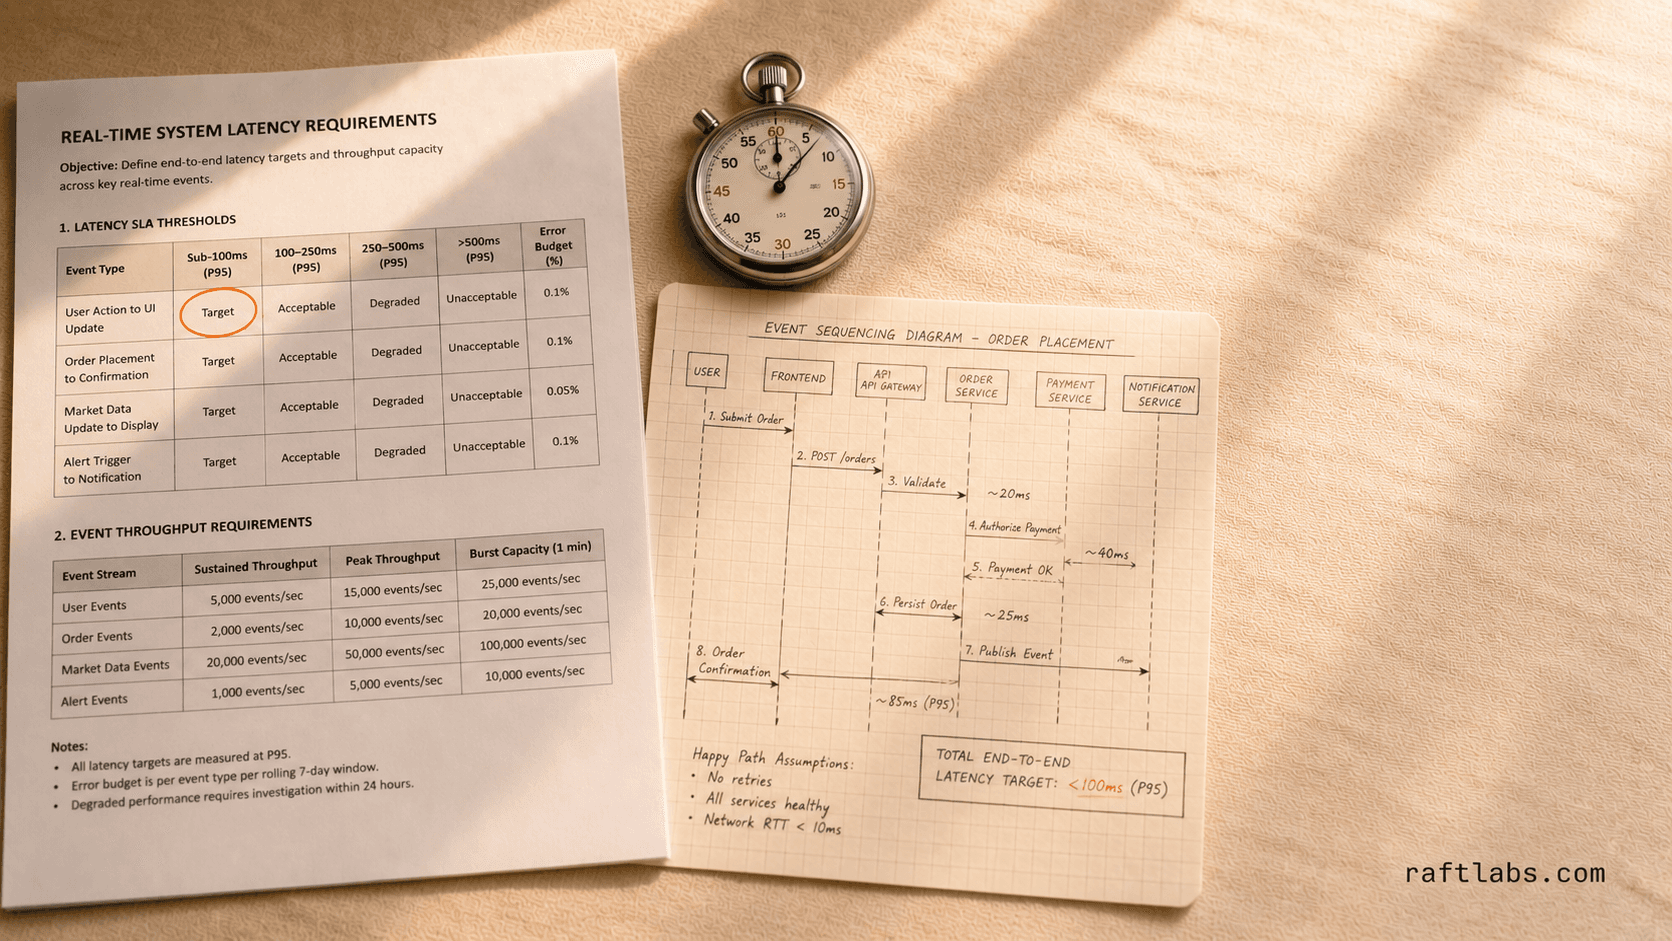
The label means little without a freshness window. A collaboration cursor may tolerate hundreds of milliseconds. An operational dashboard may tolerate seconds. A background status update may need only a minute. The architecture should match the decision a delayed event could change.
This page remains distinct from general custom software development because it addresses persistent connections, event semantics, state synchronisation, recovery, and load. It also sets a boundary: device connectivity management belongs on the IoT connectivity platform page, while a normal request-response application belongs with web development.
Performance claims require a configuration and workload. We report observed behaviour for the tested environment, traffic model, regions, payloads, dependencies, and failure cases. Product owners still decide the acceptable delay, loss, duplicate, stale state, and degraded experience.
Prefer refresh, polling, or scheduled processing when a slower path is simpler and adequate.
Users collaborate, monitor, track, dispatch, trade, communicate, or respond to events inside a defined freshness window.
The team can identify event producers, consumers, ownership, recovery rules, expected concurrency, and degraded behaviour.
Persistent connections, event fan-out, replay, or synchronisation are material product or operational requirements.
The data changes rarely and a refresh button, short polling interval, or scheduled job meets the user need.
Upstream data is unreliable and the proposed live interface would only display wrong information sooner.
The requirement is described as zero latency, infinite scale, perfect delivery, or exactly once without a bounded business definition.
System scope
| Pattern | Use it when | |
|---|---|---|
| Refresh or polling | Simple request-response updates | Changes are infrequent and small delays or redundant requests are acceptable. |
| Server-sent events | One-way server updates over HTTP | Browsers mainly receive a stream and do not need bidirectional messages. |
| WebSocket | Long-lived bidirectional connection | Interactive messaging, collaboration, presence, or low-delay commands justify connection state. |
| Queue or event stream | Durable backend distribution | Services need buffering, replay, independent consumption, and operational decoupling. |
When a connection drops, a spinner is not a recovery plan. The interface should tell users when data was last confirmed, whether a request is queued, which edits conflicted, and what can still be trusted. Reconnect storms after an outage need jitter and capacity protection. Slow consumers need batching, dropping, resync, or disconnection rules.
Event-driven backends also need business reconciliation. A message acknowledgement can confirm transport without proving the downstream state is correct. For money, inventory, entitlement, or other important workflows, periodic comparison with the system of record may matter more than an elegant delivery claim.
Delivery
Four phases make the timing, recovery, and operating model testable.
Map producers, consumers, payloads, identity, freshness, ordering, duplicates, permissions, concurrency, disconnection, degraded behaviour, and business ownership.
Choose polling, SSE, WebSocket, webhooks, queues, or streams through a thin path; test fan-out, reconnect, backpressure, latency, and cost assumptions.
Implement event contracts, state synchronisation, product UI, acknowledgements, retries, idempotency, replay, observability, security, and failure handling.
Exercise realistic traffic and faults, stage rollout, verify service objectives, document runbooks and limits, and transfer or support operations.
Constraints
Scope and price
Start with one event family, producer, consumer experience, service target, recovery path, and operating owner.
The proposal separates engineering from cloud, broker, network, observability, vendor, on-call, and support costs.
Starting investment
Starts at $20K
A focused release commonly takes 8 to 12 weeks. Collaboration, durable replay, several regions, large connection counts, device fleets, or regulated data add scope.
Tested assumptions
Capacity results name the environment and workload rather than becoming an unqualified scale promise.
Visible degraded state
Reconnect, stale data, retries, and recovery are designed as product behaviour, not hidden implementation details.
Custom Software Development
Design the broader workflow when real-time delivery is only one implementation detail.
API Development
Build stable request-response and event interfaces between products and systems.
IoT Development
Connect device telemetry, commands, edge behaviour, and fleet operations.
IoT Connectivity Platform
Manage cellular subscriptions, usage, carrier integrations, and connectivity operations.
Proof
Three-year average engagement. Founders and operators describing the work in their own words. No marketing varnish.
"Incredibly simple and easy to use app. Exactly what we were looking for."
Nuala C.
Director, BrandFire
Work with us
Bring the producers, consumers, payloads, current delay, freshness target, concurrency, network conditions, ordering needs, recovery rules, and operating owner.
Straight answers to what buyers ask before they scope. Still stuck? .
Not necessarily. Polling may be enough for infrequent changes. Server-sent events suit server-to-client streams. Webhooks notify other systems. WebSocket supports bidirectional, long-lived interaction. Queues and streams distribute backend events. A product may use several. We choose from freshness, direction, connection count, browser or mobile behaviour, intermediaries, delivery semantics, team skills, infrastructure, and cost.
Distributed systems rarely offer a useful universal exactly-once guarantee. We define the required boundary, then use identifiers, sequence data, idempotent consumers, acknowledgements, retries, durable storage, replay, deduplication, and reconciliation as needed. Ordering may be global, per entity, or unnecessary. The product must specify what a duplicate, delay, omission, or reorder means to the workflow.
Clients resume from a known cursor, sequence, timestamp, or state version where the architecture supports it. The server may replay retained events or return a fresh snapshot followed by changes. We test suspended mobile apps, expired credentials, network switching, long disconnects, deploys, partial outages, and retention gaps. The interface shows stale or reconnecting state rather than pretending it is current.
We model realistic connection ramps, active versus idle users, message sizes, event bursts, subscriptions, regions, authentication, fan-out, slow consumers, reconnect storms, and downstream limits. Load tests run against an agreed environment with observable client and server measures. Results apply to that configuration and scenario; they are not a permanent guarantee against different traffic or dependencies.
A focused workflow starts at $20K and commonly takes 8 to 12 weeks. Collaboration algorithms, several regions, durable replay, high concurrency, device networks, strict latency, regulated data, or complex legacy integration add scope. The proposal separates engineering from cloud, broker, network, monitoring, third-party, on-call, and ongoing support costs. A complete quote names the event families and producers in scope, who does what and who can see and change what, what 'done' looks like for the first live workflow, the system connections in scope, and anything left out. Any change to that scope is priced and approved in writing before the work is done.
Usually, yes. The work starts the same way: we define the event contract for one live workflow, map its producers and consumers against the systems you already run, and prove the protocol and capacity through a thin path before building the full workflow. The existing application keeps working while the live feature is built and load tested, and the rollout is staged. What decides the size of the job is how cleanly the current system can produce the events and how much recovery behaviour the workflow needs.
You do, from day one. The code, the accounts in your name, your data, and the project notes are yours from the first day of the engagement, not handed over at the end. The notes stay current as the build progresses, so another capable team could take over from them if you ever chose to move.
You already hold everything: the code, the accounts in your name, your data, and project notes that stay current through the build. There is nothing to unlock and nothing waiting on us. We do not offer source-code escrow, because nothing is held back for escrow to release. The runbooks and limits documented at handover are written so your own team or a new team can run the live workflow from them.
Penetration testing is taken care of before launch. No production data is used in development, always. Backups are tested, always. When someone leaves a team, there are offboarding steps that remove their access. Any third-party services the system depends on, such as cloud, broker, or monitoring services, are named in the scope document before you sign. We claim practices we can show you, not certifications.
Your organisation. The duties that come with the data a live system moves and stores, such as privacy and retention duties, stay with you, and they apply to systems like this one because it carries that data between people and services. The build carries the software parts scoping names, such as who can see and change what, how long events are kept, and how access is recorded. Compliance is shared, and no real-time feature makes an organisation compliant on its own.
Support is a separate arrangement we agree with you in writing: running the live workflow day to day, watching connection and delivery behaviour, and capacity checks as traffic grows, or your own team running it from the runbooks and project notes. The standing costs are in the open from the quote onward: cloud, broker, network, and monitoring costs, third-party services, and on-call cover if your workflow needs it. Those costs run whether we support the system or your team does, and the proposal separates them from the engineering price.
A focused workflow commonly takes 8 to 12 weeks. The calendar is driven less by writing code than by readiness around it: the release comes after producers and integration environments are ready, the load test needs an agreed environment and a realistic traffic model, and the rollout is staged rather than switched on for everyone at once. The scope document gives the dates for your workflow in writing once those inputs are known.
We work on five remote work principles. Switch to Async: the state of the build is readable without waiting for a meeting. Be Prepared: calls come with the event contract, the open questions, and the decisions needed. Write: decisions about ordering, delivery, and recovery are written down, not left in call memory. Ask and tell: a capacity or recovery problem is said plainly and early, not at the deadline. Own: the people on your project own their parts end to end.
Yes. We sign your NDA before anything sensitive is shared, and the details you give us for scoping, such as your event volumes, current delays, and system layout, stay confidential.
No. The people on your calls are the people on your project, from the event contract to the load test and handover. Our team works across India and Ireland, and the engineers who scope your workflow are the ones who build it. Nothing is passed to a subcontractor or a separate delivery team.