AI Proof of Concept Development
An AI proof of concept for a decision, not a demo.
Bring one claim about quality, data, latency, cost, integration, or human review. We agree what passing means before tuning begins, test the smallest credible approaches on representative examples, and hand over the evidence for a go, narrow, change, or stop decision.
Bring one expensive assumption. Leave knowing what an honest proof would need to test.
Trusted by
























The brief
Start with what is not working.
Good software decisions begin with the constraint, not a list of features or a preferred technology.
A convincing demonstration works on prepared examples, but nobody has tested the awkward cases from the real queue.
Leadership wants evidence before approving production, but the team has not agreed what success or acceptable failure means.
A prototype exists, yet its data, evaluation, reviewer effort, integration limits, and cost at real volume remain unknown.
Plain answer
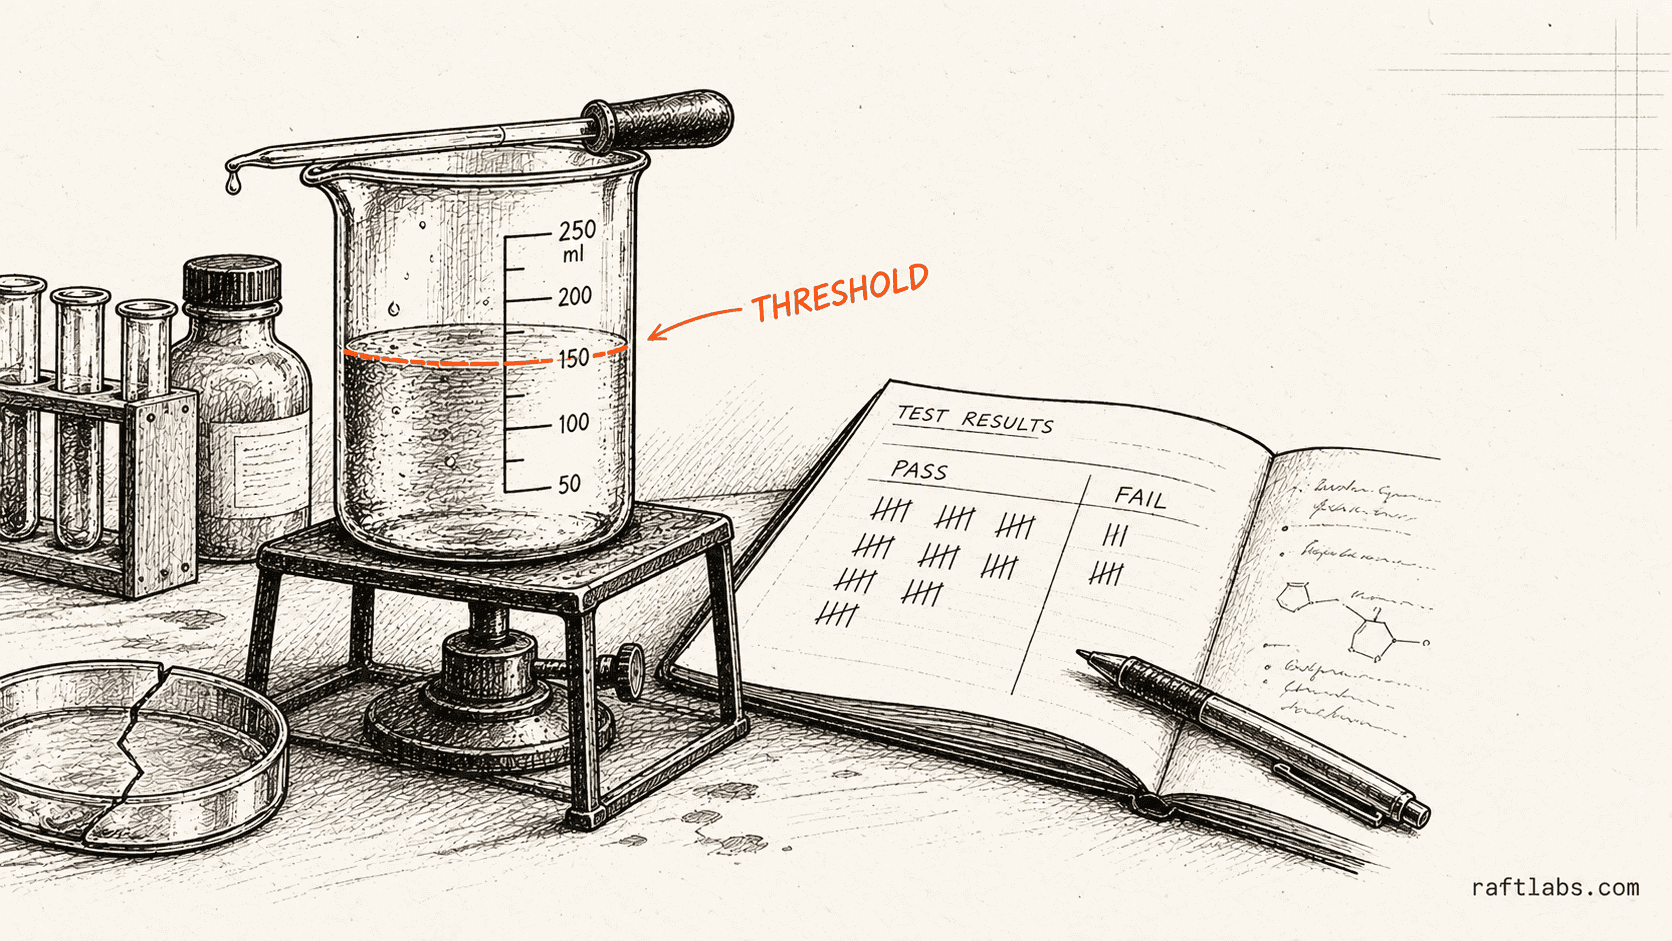
An AI proof of concept tests whether one selected AI approach can meet an agreed threshold on representative data before a production investment is approved. It measures task quality, important failure cases, latency, unit cost, human-review effort, and integration constraints. Scope and price are written down before the phase starts.
What to remember
- A PoC tests one consequential uncertainty, not a small version of the entire product.
- The success threshold, trade-offs, and holdout examples should be agreed before the final evaluation.
- A no-go result is useful when it prevents a larger investment or exposes a narrower path that can work.
- A PoC ends with measured results, failure cases, limitations, operating implications, and a go, narrow, change, or stop recommendation.
- Production cost is estimated from the PoC per completed useful result as well as a monthly range, not from the cost of the demonstration alone.
A demo can impress everyone and prove almost nothing.
Five clean examples can return five clean answers. That shows the interaction is possible. It does not show whether the approach will survive older documents, incomplete fields, conflicting sources, unusual wording, weak images, new customer behaviour, or the mistakes that cost the business most.
Consider a team testing whether AI can extract information from incoming documents. An overall score of 92% sounds promising. The number becomes less useful if totals are almost always right but customer identifiers fail often enough to send records to the wrong account. The business may tolerate a missing optional note and reject a single incorrect payment value. Both errors count equally inside a simple accuracy average, but they do not carry the same cost.
A useful PoC fixes those distinctions before tuning begins. It groups representative cases, defines the errors that require review or rejection, preserves an unseen holdout, and measures the smallest credible approaches. The result can be a go, a narrower human-assisted workflow, a different approach, or a stop. That decision is the product of the PoC.
Test design
A decision-grade PoC changes what gets measured.
A polished prototype optimises for belief. An honest proof optimises for a decision another team can inspect.
- Prepared examplesThe clean cases used during development make the result look more dependable than the real queue.
- Success defined afterwardsThe most flattering metric becomes the headline after the team has seen the result.
- One average scoreImportant false accepts, refusals, edge cases, and affected groups disappear inside an overall percentage.
- Prototype-only economicsA few model calls look cheap while retries, review, integration, monitoring, and support remain uncounted.
- Representative case groupsNormal, difficult, costly, incomplete, and prohibited cases are identified before the final test.
- Threshold fixed firstThe measure, minimum result, trade-offs, and decision rule are agreed before evaluation.
- Failures remain visibleResults show where the approach works, where it needs review, and where it must refuse or stop.
- Production estimateObserved usage, latency, reviewer effort, and integration findings are translated into plausible operating cost.
The first decision is not what to build.
It is whether software is the right answer at all. We use four possible recommendations before discussing a development scope.
- 01
Buy
Choose a maintained product when it handles the core workflow and the remaining gaps can be solved with configuration, a connector, or a small process change. Paying for software you do not have to maintain is often the better trade.
- 02
Repair
Keep the existing product when users still get value from it and the code can be understood safely. Start with evidence: where the code lives, how the data is organized, what is tested, which outside services it depends on, who can access what, and how updates go live.
- 03
Build
Own the system when the workflow shapes margin, customer experience, speed, or a product customers pay for. Start with one complete path and the system connections that path cannot work without.
- 04
Wait
Do not turn a changing policy into permanent software. Stabilise the rules, name the workflow owner, and measure the cost of the current process before paying for a product.
Not sure which path is yours? Bring it to a 30-minute call. Leave with the answer in writing.
Fit
A PoC needs one testable uncertainty and someone prepared to act on it.
The starting point is a selected use case, access to representative evidence, and a decision rule agreed before the result is visible.
The use case is selected, but quality, data readiness, latency, cost, reviewer effort, or integration feasibility is still uncertain.
Representative examples and the people authorised to judge disputed results can be made available.
A sponsor can approve, narrow, change, or stop the production investment based on the recorded evidence.
The team still needs to choose among several AI opportunities; start with AI consulting.
The main uncertainty is whether customers want the product; use an MVP or controlled pilot.
The expected result is a fully integrated, hardened, supported production system on a PoC scope.
If there is no decision the evidence can change, the team does not need a PoC yet. It needs a clearer question.
Demo, prototype, PoC, or pilot?
| Artefact | Primary question | Evidence | Useful next decision |
|---|---|---|---|
| Demo | Can we communicate the possible experience? | Selected or prepared examples | Is the idea worth exploring? |
| Prototype | How might the experience or technical approach work? | Interactive flow or experimental version | What should we test or design next? |
| AI proof of concept | Can one approach clear a defined threshold? | Representative set, holdout, measurements, and failure record | Go, narrow, change, repeat, or stop |
| Pilot | Will a controlled real-world group use and operate it successfully? | Live workflow, adoption, reliability, support, and outcome evidence | Expand, revise, pause, or retire |
Proof questions
Different AI ideas need different evidence.
The PoC is shaped around the claim that could break the business case, not around a fashionable model category.
Can it answer from approved sources?
Test whether a retrieval or generative system finds the right material, cites it, refuses unsupported questions, respects permissions, and still responds within the required time and cost.
Can it read the documents people actually send?
Measure classification and field extraction across real layouts, scans, handwriting, missing pages, ambiguous values, languages, and the errors that require human review.
Can it predict or rank better than the current method?
Compare the model with the existing baseline using an honest time split or holdout, useful business thresholds, relevant groups, and the false-positive or false-negative trade-off.
Can it handle a real conversation?
Test understanding, response quality, interruption, latency, accents, silence, escalation, prohibited requests, and whether a person can recover the interaction when the system loses context.
Can an agent complete a controlled task?
Measure the full sequence of tool use, not only the final message. Include permissions, duplicate steps, confirmation, refusal, rollback, and what happens when a connected system fails.
Can the economics survive real usage?
Observe model calls, retrieval, retries, storage, latency, reviewer time, and integration effort, then estimate cost per completed useful result at expected and peak volume.
How much data is enough for an AI proof of concept?
There is no honest universal number. A receipt-extraction test with four stable layouts asks a different sampling question from a support assistant that must search thousands of changing documents. A prediction model for a rare event needs a different evaluation from a voice agent handling common appointment calls.
Start by listing the input families that could change the result. For documents, that may include layout, image quality, language, missing pages, handwritten fields, and older formats. For retrieval, it may include source type, permission level, conflicting guidance, date, and questions the system should refuse. For prediction, it may include time periods, relevant user or customer groups, rare outcomes, and shifts between training and future use.
The evaluation set should contain enough examples from each important group to expose material failure patterns. It should also preserve a final holdout that is not used to adjust prompts, rules, or models. If the sample is too small to estimate a claim, the handover should say so plainly and limit the decision to what the evidence can support.
How it works
Fix the test before building the proof.
Each phase removes one way a PoC can mislead the production decision. The final readout keeps the result, its limits, and the remaining work visible together.
- 01Define
Fix the proof question
Which uncertain claim could change the investment decision?
Follow the current workflow and separate what is already known from what is assumed. Translate the broad request into one question that a bounded experiment can answer.
Decision produced
One user, task, current baseline, expensive uncertainty, primary measure, trade-offs, prohibited outcomes, and a go or no-go rule.Risk closed
Building a small product that demonstrates many features while proving none of the assumptions holding the business case together. - 02Prepare
Build an honest evaluation set
Does the test represent the work the system will actually receive?
Review representative examples with the people who understand the work. Include the incomplete, ambiguous, rare, costly, and prohibited cases before choosing the final approach.
Decision produced
A data record covering rights, sources, case groups, labels or rubrics, known gaps, tuning examples, and a protected final holdout.Risk closed
Optimising for the clean or familiar cases until the PoC passes a test that production will never resemble. - 03Test
Prototype and measure
Which smallest credible approach clears the agreed threshold, and where does it fail?
Compare only the approaches needed to resolve the decision. Record model, prompt, rule, data, and configuration changes so the result can be repeated and challenged.
Decision produced
Reproducible results for quality, case groups, failures, latency, unit cost, reviewer effort, and any integration condition material to the choice.Risk closed
Reporting one flattering average while important failure types, manual recovery, and operating cost remain invisible. - 04Decide
Make the production call
What does the evidence justify funding next?
Review the evidence with the sponsor, subject-matter reviewer, and technical owner. Keep what remains unproved next to the recommendation instead of hiding it in an appendix.
Decision produced
A go, narrow, change, repeat, or stop recommendation with limitations, transferable assets, production gaps, architecture direction, budget range, and the next decision gate.Risk closed
Calling the prototype production-ready or treating a technical pass as proof that users, security, operations, and economics are already solved.
Test integrity
Four mistakes can turn a PoC into a sales demonstration
- A moving threshold
- Agree the measure, target, tolerance, and allowed trade-offs before the final evaluation. Do not redefine success after seeing which metric looks strongest.
- Clean-sample bias
- Include incomplete, ambiguous, older, rare, prohibited, and operationally expensive cases instead of testing only examples that already worked during development.
- Data leakage
- Keep tuning examples separate from the final holdout and record changes. Repeatedly adjusting the approach against the holdout makes it part of development data.
- Prototype economics
- Estimate production traffic, retries, infrastructure, human review, monitoring, support, and integration. A low-cost experiment does not guarantee a viable service.
What the handover should make inspectable
A production team should be able to understand the result without depending on a confident presentation or repeating the experiment from memory.
- 01
The test can be reproduced
The handover records data versions, models, prompts, settings, rules, code, environment, and the exact evaluation procedure used for the final result. - 02
The failures have names
Results are grouped into useful failure classes with examples, frequency, business consequence, and the proposed response: accept, review, refuse, retry, or stop. - 03
The result stays inside its evidence
A score from one sample, language, location, time period, or workflow is not presented as proof for populations and conditions that were never tested. - 04
Production gaps remain visible
Permissions, security, monitoring, integration, migration, user experience, support, compliance review, scale, and operating ownership are listed even when they sit outside the PoC.
What it costs
Every project starts at $10K.
The first phase tests one claim about quality, data, latency, cost, integration, or human review, with pass criteria agreed before tuning starts.
Starting investment
Starts at $10K
Bring one claim and we agree what passing means before any model work begins. After a 30-minute call, you get a written build, buy, repair, or wait recommendation plus first-phase direction. Free, whether or not you build with us.
Choose the next decision, not the next buzzword.
The adjacent path depends on whether the uncertainty is strategic, technical, commercial, or operational.
- 01
AI Consulting
Rank competing opportunities, assess readiness, and decide where an investment or proof should come first.
- 02
MVP Development
Test whether real users will adopt and value a usable product, not only whether the AI technique can work.
- 03
AI Development
Turn supported assumptions into integrated, monitored software with human review, cost control, and operating ownership.
- 04
Musgrave receipt case study
Inspect a recorded AI validation result, the engineering change behind it, and the limits of the published evidence.
Proof
What clients say about working with RaftLabs
Three-year average engagement. Founders and operators describing the work in their own words. No marketing varnish.
Raftlabs is not only our partner, but an integral part of our team and startup!
Tedo S.
CCO and CTO at Fore Coffee
Work with us
Bring one AI claim that needs an honest test.
In a 30-minute call, we will help you turn the claim into a proof question, identify the evidence it needs, and tell you whether a PoC is the right next step.
- The selected user, task, and current way the result is produced.
- Representative examples, including the incomplete or unusual cases demos avoid.
- The quality, cost, speed, review, or integration claim that remains uncertain.
- One owner prepared to proceed, narrow, change, or stop when the evidence arrives.
Frequently asked questions
Straight answers to what buyers ask before they scope. Still stuck? .
An AI proof of concept is a bounded technical experiment that tests whether one selected AI approach can solve a specific task under representative conditions. It begins with a current baseline, success threshold, trade-offs, and decision owner. It ends with measured results, failure cases, limitations, operating implications, and a go, narrow, change, or stop recommendation.
It should validate the uncertainty that could change the investment decision. That may be output quality, data readiness, retrieval coverage, prediction performance, action reliability, latency, unit cost, human-review effort, or integration feasibility. The PoC should also expose where the approach fails and what production would still require. It should not attempt to prove every feature at once.
A demo communicates a possible interaction, often with selected examples. A prototype explores how the experience or technical approach might work. A proof of concept measures one uncertain claim. A pilot runs a more complete solution with a controlled real-world group or workload. An MVP is a usable product released to test customer or operating value. Teams can combine artefacts, but the decision each one supports should remain explicit.
Run a PoC when one uncertain assumption could make the larger build unwise. Common examples include unknown quality on your documents, unreliable answers from your knowledge base, uncertain prediction lift, unacceptable reviewer effort, or model cost that may not work at expected volume. Start development when the core evidence is already credible and the remaining work is integration, product behaviour, controls, and operation.
Start with AI consulting when the organisation still needs to choose among several use cases, compare build and buy paths, assess broad readiness, or agree where AI belongs. Start with a PoC when one use case is selected and a testable technical or economic question remains. Consulting chooses the investment; a PoC measures the riskiest assumption inside it.
You need examples that represent the task, difficult cases that could change the decision, permission to use the data, context for the correct outcome, and people who can judge disputed results. The amount varies by task and variation. The first step checks missingness, coverage, leakage, privacy, time drift, relevant groups, and whether a separate holdout can support an honest final evaluation.
There is no universal sample size. A narrow extraction task with a few stable layouts may need fewer examples than a prediction problem with many outcomes or a retrieval system covering thousands of documents. The useful question is whether the set represents the important input families and can estimate the errors that matter. We document the sample, its limits, and which claims it cannot support.
Begin with the current method and the cost of different mistakes. Then define the primary task measure, acceptable false positives and false negatives, review threshold, prohibited outcomes, latency, cost per useful result, and any minimum coverage. Agree which trade-offs are allowed before the final test. A single accuracy percentage can hide the failure that makes the workflow unusable.
Separate examples used for exploration and tuning from a final holdout that remains unseen until the approach is fixed. Record data versions, prompts, models, settings, rules, and changes. Group results by meaningful input types instead of reporting only an overall average. If the holdout is used repeatedly for tuning, it is no longer an honest independent check.
The warning signs are familiar: the PoC extends with no decision, no executive sponsor, and no budget for scaling. Three questions end pilot purgatory: name the specific problem in one sentence; state what success looks like in 90 days as a number; confirm what data the test needs and whether it is available. A PoC is a decision-making exercise, not a contest to push one accuracy number higher: define success criteria, failure criteria, and a timebox before the work starts.
The model is good, but the realistic deployment scenario plus infrastructure are the hard parts. The full cycle is not just modeling: finding the right data, deploying it, monitoring it, feeding data back, showing safety. Many AI systems cost more to maintain than the problems they solve. That operating gap is what stalls scaling. A demo can impress everyone and prove almost nothing.
A no-go can be a successful outcome when it prevents a larger investment. The decision record explains whether the gap came from data, task definition, model capability, workflow design, reviewer burden, integration, or economics. It can recommend a narrower task, a human-assisted path, another approach, more evidence, ordinary automation, or stopping. The threshold is not rewritten after the result arrives.
Measure model or inference usage, retries, retrieval, storage, infrastructure, latency, and reviewer time during the experiment. Then model them against plausible volume, peak demand, provider pricing, monitoring, support, and failure recovery. The estimate should be expressed per completed useful result as well as a monthly range. A cheap demonstration can still imply an expensive production service.
Yes. The PoC can use a representative export, approved test environment, sandbox API, or a thin integration when that is enough to test the uncertain claim. If the decision depends on live permissions, latency, write-back, concurrency, or failure behaviour, those boundaries need a more realistic connection. Production migration, complete security hardening, broad user roles, and operational support remain separate unless explicitly included.
Timing moves with data access, labelling, the number of approaches compared, domain-expert availability, evaluation complexity, hardware or live-system dependencies, and formal security or risk review. The calendar holds more than the prototype itself: fixing the proof question and success threshold, building the evaluation set and its labels or scoring guides, testing the approaches against the holdout, and the decision readout with your sponsor. Dates slip most often while waiting for data access or for the people who can judge disputed results, and when the proof question or threshold changes mid-build. This page publishes no standard duration, because the honest answer depends on those items. The schedule, activities, evidence, dependencies, and decision date are agreed before the phase starts.
Every project starts at $10K for the first phase. A bounded first phase covers one proof question, representative data review, an evaluation set, the smallest credible prototype, measurement, failure analysis, and a decision record. A complete quote names the proof question, the data and evaluation work, the approaches compared, any labelling or live integration the test needs, and what 'done' looks like, agreed in writing before tuning begins. Scope grows when the test needs extensive labelling, several model families, specialist hardware, complex data access, live integration, or regulated evidence. Scope and price are written down before the phase starts, and any change is priced before you approve it.
The handover includes the proof question, baseline, data and sampling record, evaluation method, thresholds, tested approaches, results by meaningful case group, failure taxonomy, latency and cost evidence, limitations, experiment assets where rights allow, and a production recommendation. It also names what remains unproved, what production would require, and the condition for approving another phase.
You own the project-specific code, prompts, configurations, evaluation artefacts, and agreed project IP from day one, and your data stays yours throughout. The accounts the proof runs on, including model provider accounts, are opened in your name from day one where the provider allows it, so you hold the keys during the work, not only at handover. Third-party models, services, datasets, and open-source components retain their own licence and service terms. Any data or asset that cannot be transferred because of rights or security constraints is identified before the phase starts.
You already hold what another team would need. The code, prompts, evaluation assets, and decision record are yours from day one, the accounts run in your name, and the handover record names the data, method, thresholds, results, and limitations in plain terms. There is nothing to extract from us before a new team can continue, whether you move because the proof is done, because you choose a different partner for production, or because we stop trading.
Security here is day-to-day practice. Penetration testing is taken care of. Live production data is not used in development, always: the proof works on the representative export, approved test environment, or sandbox agreed in the scope, not on your live systems. Backups are tested, not just taken. When someone leaves a team, offboarding steps remove their access. The third-party services the proof depends on, including model providers and any service that processes your data, are named in the scope document before you sign, because a problem at one provider can reach everyone connected to it, as the October 2026 provider breaches showed. Your industry may also impose its own rules on a system like this; scoping identifies which ones apply. We claim practices we can show you, not certifications.
A proof of concept ends with a decision, not a running service, so there is no support arrangement to continue unless you approve production. If the decision is go, the operating notes from the handover let your own team run the system, or we can agree another fixed phase or an ongoing engagement. Whoever runs it, production carries standing costs that exist from the first day live: hosting, model and API usage, connected third-party services, monitoring, platform updates, and security patches. The proof measures the usage behind those costs, so the production estimate names them before you sign, rather than leaving them to be discovered after launch.
We work on five principles. Switch to async: most updates are written, so you can read and reply in your own time instead of waiting for a meeting. Be prepared: calls cover decisions already framed in writing, not first sight of the material. Write: the proof question, thresholds, results, and decisions are recorded where both sides can see them. Ask and tell: questions and bad news travel early, including a result heading below threshold. Own: a named person on our side is responsible for the work and for telling you where it stands. Progress is visible as measured results and the decision record taking shape, not as reported percentages.
Yes. We sign your NDA before anything sensitive is shared, including the examples and data the proof would test. The NDA is the first protection, not the only one: the stronger protection is structural, because you own the code, prompts, and evaluation assets from day one and the accounts run in your name. Share the problem and the users first; the detailed data and documents follow once the paperwork is signed.
No undisclosed handoff. The team that scopes your proof is the team that builds and measures it, and you can talk to the people doing the work directly. Our teams are based in India and Ireland. Model providers and connected services are tools the proof calls, named in the scope; they are not a team your project is passed to.
Yes, AI is part of how we work, and it runs through a structured process we call RaftKit rather than open-ended prompting. The work moves through five phases, Blueprint, Plan, Build, Review, and Compound, and each phase has quality gates the work must pass. Review happens in two stages: first, whether the work matches what was asked for; second, a wider check by specialised AI reviewers looking at separate concerns such as security, quality, and test coverage. Findings are graded by seriousness, and a serious finding blocks the work from shipping until it is fixed. A named person stays accountable for what reaches your proof, so an AI suggestion becomes part of your system only after it has been checked.