"Thanks to RL Remotely team for experimenting with an innovative remote work application for employee engagement and enterprise productivity."
Mohit S.
Founder, WorxRemotely
Data Engineering Services
When finance, sales, and operations define the same customer or transaction differently, another dashboard adds another argument. RaftLabs develops data pipelines, warehouses, shared models, and quality checks that turn disconnected operational systems into a dependable reporting and AI foundation.
Bring the problem, the current workflow, or the existing code. We reply with a practical next step within one business day.
The brief
Good software decisions begin with the constraint, not a list of features or a preferred technology.
Does the same revenue, customer, or inventory question produce a different answer in every team?
Are analysts rebuilding joins and cleaning exports before they can answer the actual question?
Plain answer
Data engineering services connect source systems, standardize business definitions, and deliver trusted data for reporting or AI. RaftLabs develops batch and real-time pipelines, warehouses, and quality checks. A focused warehouse for 3 to 5 sources starts at $30K and takes 8 to 12 weeks.
What to remember
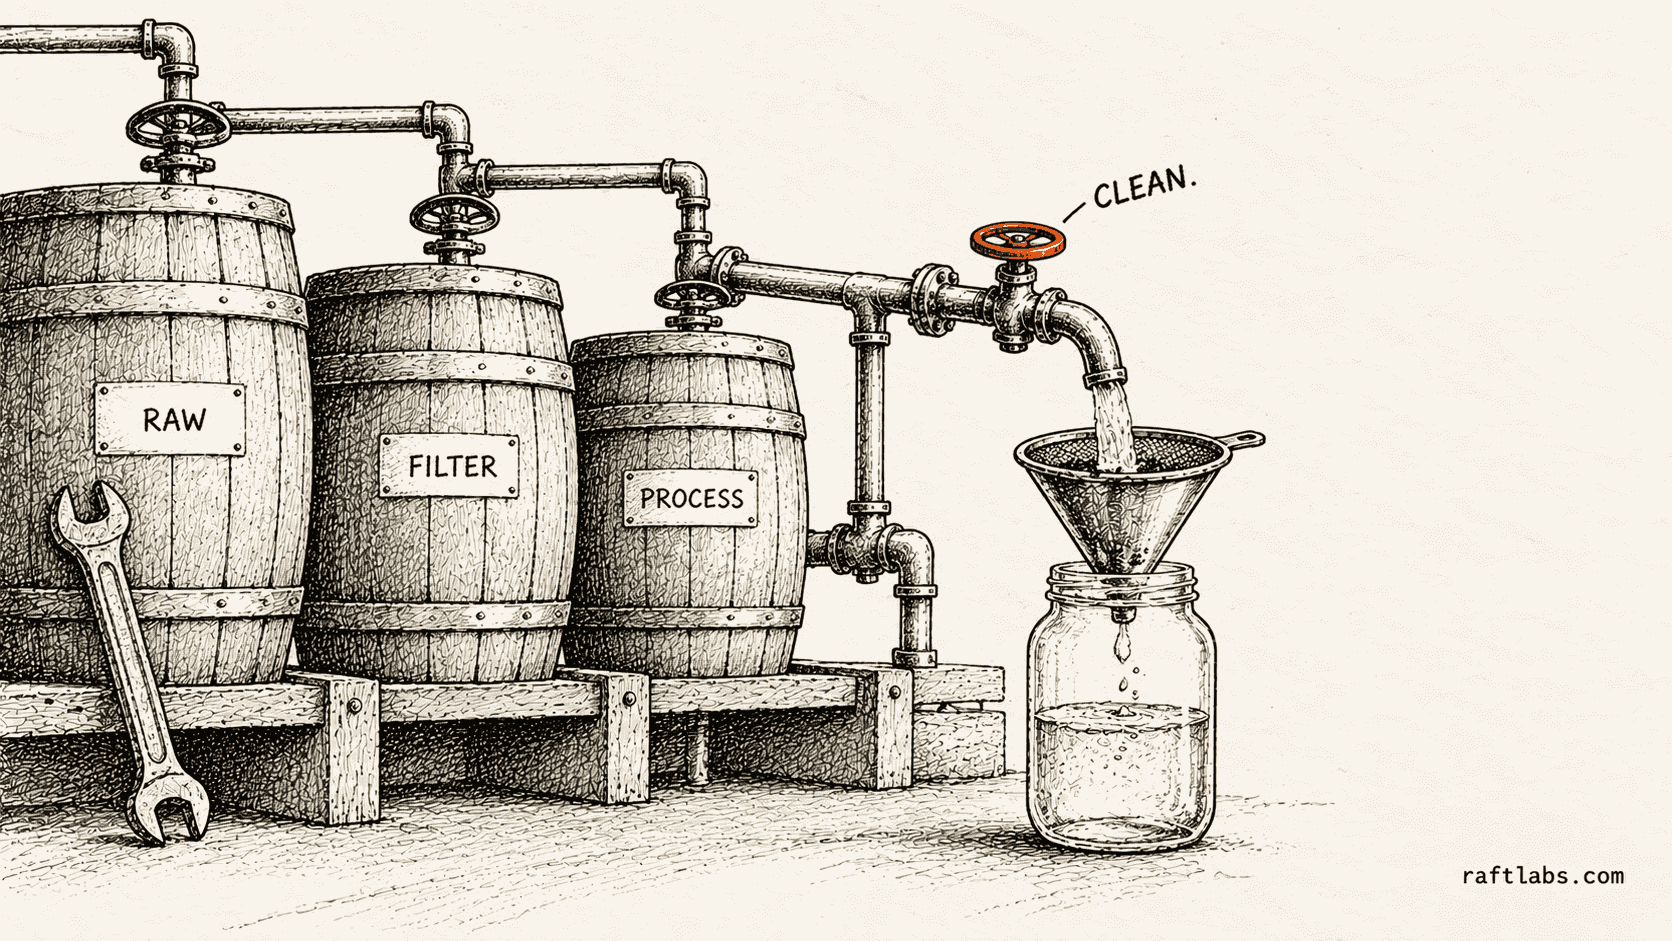
Finance starts with the ERP. Sales starts with the CRM. Operations trusts the warehouse system. Someone joins the files, changes a filter, and arrives with a fourth version of revenue by customer.
Data engineering removes the repeated reconciliation. It gives the business one documented definition, one refresh path, and a visible failure when a source does not arrive as expected.
Proof
A configured connector and reporting tool are better when the sources are clean and the definitions already agree.
Several operational systems hold overlapping customers, products, transactions, or events.
Teams repeatedly clean, join, and reconcile exports before analysis can begin.
A named owner can approve shared definitions, source precedence, access, and the first subject area.
One clean source and a standard reporting connector answer the current questions.
The business cannot yet agree which decisions or metrics the data product should support.
The request is for a dashboard while the underlying definitions remain disputed.
Scope
| Configured platform | Custom data engineering | |
|---|---|---|
| Best when | Common sources and standard reporting needs | Proprietary sources, identity rules, or operating logic matter |
| Connectors | Use the vendor's supported source and destination catalog | Develop around the exact interface and failure behaviour |
| Business logic | Model standard entities inside platform conventions | Encode approved definitions and source precedence |
| Operations | Monitor the vendor service and configured jobs | Own pipeline tests, alerts, recovery, and documentation |
| First step | Trial representative sources and reports | Prove one subject area from source to accepted output |
We recommend configuration when it solves the problem cleanly. Custom work fits when identity resolution, source quirks, business logic, or reliability gaps remain after the standard connectors are exhausted.
Mining analytics begins with governed records, not dashboards. The path runs from collar and interval through sample, laboratory result, QAQC review, versioned export, and downstream interpretation. The chain from source record to reviewed decision matters more than any dashboard.
Map project, hole, interval, sample, dispatch, certificate, assay, unit, method, location, equipment, or production identifiers, and ingest through supported files or APIs with schema, type, range, duplicate, and completeness checks. Failed records enter a visible exception queue.
Applies client-approved rules to control samples, intervals, units, revisions, and other selected records. Reviewers see source evidence and record a reason for approval, rejection, or override. Corrections create new versions rather than erasing the history behind earlier outputs.
Come from approved snapshots that preserve record versions, validation state, filters, mappings, coordinate reference, units, and reviewer; the export is tested against the receiving geological, planning, reporting, or analytics product.
Show completeness, turnaround, exception age, failed imports, unresolved controls, and publication status first, with data owners, review queues, access by project or role, retention, monitoring, and recovery so the workflow can be operated after launch.
Laboratory assay integration is confirmed, not assumed: the laboratory interface, certificate, sample identifier, units, detection limits, expected analytes, revisions, and rejection behaviour are tested with representative and malformed files or APIs. The client defines its sampling and QAQC protocol; the software records rules, results, review, exceptions, and approved overrides without replacing specialist judgement. Data freezes preserve the exact record versions and filters used for an export, so later corrections do not silently change the evidence behind an earlier decision. Export compatibility with geological or resource tools is confirmed during discovery with the receiving team: field mappings, units, coordinate references, null handling, validation status, and version rules.
OT and IT integration is often the hardest part of a deployment: machine operations tech and control-room IT were built on incompatible protocols, and bridging them without latency or security vulnerabilities takes deliberate design.
Private LTE or 5G lets safety-critical telemetry be prioritized; confirm spectrum access and regulatory status in the mine's jurisdiction.
Trade-off
Buy before build applies here: most teams should configure established mining or geological products and strengthen data pipelines first. Custom development fits when a valuable data model, QAQC, access, reconciliation, or workflow constraint remains after testing products and integrations. Geological interpretation, resource estimation, reporting definitions, and regulatory decisions stay with the client's qualified specialists.
How it works
Start with one subject area and make each definition and reconciliation test visible.
Choose the reports, workflows, or AI uses the first data product must support. Inventory the source systems, owners, refresh needs, access limits, and manual reconciliation used today.
Map identifiers and record grain. Decide which source wins when values conflict, how history behaves, and who approves the shared definitions for core entities and metrics.
Load representative history, apply the approved logic, and test freshness, completeness, schema, relationships, and duplicates. A failed check stops or labels the affected output before a report or model consumes it.
Reconcile warehouse totals and sample records with each source. Document ownership, alerts, repair steps, and known limits. Add another domain only after analysts and business owners accept the first one.
RaftLabs built a gas-station management platform with AI OCR that connected 40+ locations during beta. A lightweight local utility synchronized data from existing point-of-sale systems every 10 minutes and kept records locally when a station lost connectivity.
The platform processed more than 20K transactions in one test day. Those figures describe that system and rollout; they are not a universal capacity promise for another data stack.
Start from the foundation you need: a warehouse that answers questions, pipelines that move data, or real-time streams.
Scope and price
A focused first release covers three to five sources, core entities, quality checks, and a useful analytical layer.
Add more domains or real-time movement only after the first output reconciles with the source systems and users accept its definitions.
Starting investment
Starts at $30K
A focused warehouse commonly takes 8 to 12 weeks. Source access and reconciliation complexity move the estimate most.
Data audit before the build
We inspect representative source data and interfaces before fixing the phase scope and price. Unknown access or quality problems stay visible rather than becoming quiet assumptions.
Fixed-price phase
Once the sources, definitions, and acceptance checks are agreed, the first phase price is locked in writing. Changes require approval before work begins.
Proof
Three-year average engagement. Founders and operators describing the work in their own words. No marketing varnish.
Incredibly simple and easy to use app. Exactly what we were looking for.
Nuala C.
Director, BrandFire
"Thanks to RL Remotely team for experimenting with an innovative remote work application for employee engagement and enterprise productivity."
Mohit S.
Founder, WorxRemotely
Work with us
We will trace it to the source systems, definitions, and smallest data product that can settle the number.
Straight answers to what buyers ask before they scope. Still stuck? .
Data engineering services design and develop the pipelines, storage, models, and quality controls that move operational data into a dependable form for reporting, analytics, or AI. A project may include ETL or ELT, a warehouse or lakehouse, shared business definitions, orchestration, monitoring, access, and documentation.
ETL transforms data before loading it into the destination. ELT loads source data first and transforms it inside the target platform. The right choice depends on data sensitivity, volume, source constraints, audit needs, available compute, and how often business logic changes. We choose after mapping those boundaries.
A warehouse is useful when several systems must support repeatable analysis through shared entities and metric definitions. It may be unnecessary when one reporting tool over one clean source answers the questions. The first assessment should name the decisions and reconciliation failures before choosing a platform.
A focused warehouse covering three to five source systems starts around $30K and commonly takes 8 to 12 weeks. Cost grows with source complexity, history, data quality, custom connectors, real-time requirements, access controls, retention, and the number of subject areas.
AI systems need governed access to current, well-defined data. Data engineering can prepare training data, features, retrieval sources, event streams, and evaluation records. It does not make an AI use case valuable by itself; the model or product still needs its own success criteria and operating controls.
Yes, after the laboratory interface, certificate, sample identifier, units, detection limits, expected analytes, revisions, and rejection behaviour are confirmed. We test representative and malformed files or APIs. The client defines its sampling and QAQC protocol; the software records rules, results, review, exceptions, and approved overrides without replacing specialist judgement.
Rules can flag missing intervals, duplicate samples, control-sample results, unit conflicts, or other client-approved conditions. A reviewer then accepts, rejects, or documents an exception. Approved snapshots preserve the exact record versions and filters used for an export, so later corrections do not silently change the evidence behind an earlier decision.
Yes, when the target product exposes a supported import format or interface. We define field mappings, units, coordinate references, null handling, validation status, and version rules with the receiving team. Exports are tested against representative projects; compatibility is confirmed during discovery rather than promised for every vendor or custom configuration.
Machine operations tech and control-room IT were built on incompatible protocols; bridging them without latency or security vulnerabilities is often the hardest part of a deployment. We assess hardware, software, and integration effort as separate risk drivers.
Continuous coverage depends on three layers at once: data coverage across the mobile fleet, a private network with quality of service, and a software layer that makes the data actionable. Private LTE or 5G lets safety-critical telemetry be prioritized; confirm spectrum access and regulatory status in the mine's jurisdiction. Reliable connectivity in remote locations is difficult but essential for real-time transmission.
The choice depends on your cloud, workload, concurrency, data formats, governance needs, team skills, and cost model. Snowflake fits many cross-cloud analytical teams; BigQuery suits GCP-native operations; Redshift aligns with established AWS estates; Databricks fits mixed engineering and machine-learning workloads. We document the tradeoff before procurement.
A pipeline is enough when data must move into an existing, fit-for-purpose destination. A warehouse is justified when several sources need shared historical models, governed metrics, analytical performance, and controlled access. Many projects need both, but the two decisions should not be disguised as one vague data-platform scope.