Data Extraction Automation Services

Data extraction automation for sources that refuse to line up.

Collect from websites, portals, emails, APIs, and files, then validate and deliver records in the schema your systems use.

Bring the sources, the destination, and one feed your team no longer trusts. Leave with a buy, integrate, build, narrow, or wait recommendation.

Recorded multi-source product

GrantHub

RaftLabs built a searchable directory that normalises grants and tax credits from fragmented official sources, then keeps the catalogue current through scheduled checks and review.

1,600+
active listings in the recorded catalogue
21
countries represented

The brief

Start with what is not working.

Good software decisions begin with the constraint, not a list of features or a preferred technology.

01

Analysts still download files, rename columns, fix categories, and remove duplicates before the data can be used.

02

A scheduled scraper or export can fail quietly after a portal changes, while the dashboard continues to refresh with incomplete data.

03

The records arrive, but nobody can trace a value to its source, judge its freshness, or explain why two sources disagree.

Plain answer

Data extraction automation collects information from websites, portals, APIs, emails, files, or legacy systems, then validates and normalises it before delivery to a database, warehouse, spreadsheet, or business application. RaftLabs data extraction projects start at $9,500.

What to remember

  • Use a maintained API, export, or data provider when it supplies the required records with acceptable rights, freshness, and cost.
  • Custom extraction is most useful when several sources must become one proprietary schema or a fragile feed creates repeated manual repair.
  • A production feed needs source lineage, validation, duplicate handling, change detection, retries, reconciliation, and an owned recovery path.

Fit

Custom extraction should remove repeated reconciliation, not create another fragile feed.

The case is strongest when the same sources matter every week, the destination schema is owned, and a missing or wrong record has a measurable consequence.

A fit
01

People repeatedly collect, clean, rename, join, or check data from the same websites, portals, exports, emails, or APIs.

02

The useful result requires several sources, a proprietary schema, business validation, entity matching, or delivery inside an existing product.

03

A process owner can provide authorised access, representative records, known failures, and acceptance criteria for freshness and quality.

Not a fit
01

An official API, bulk export, licensed feed, or maintained product already meets the requirement with less operating responsibility.

02

The work is a one-time collection small enough to complete and verify manually.

03

Access or reuse rights are unclear, or the request depends on defeating controls protecting non-public data.

A useful first recommendation can be to buy a dataset, use an API, configure a tool, repair the data contract, or retain a manual check. Custom development has to earn its maintenance cost.

The dashboard refreshed. The feed underneath it had already gone stale.

A commercial team pulls product and eligibility data from several public and partner sources. One portal changes a field label. Another starts returning only the first page. A scheduled job finishes without crashing, so the dashboard remains green and the business keeps using yesterday's incomplete result.

The visible problem appears days later. An analyst finds a missing category, downloads three exports, repairs the rows in a spreadsheet, and cannot tell which downstream records need to be corrected. The automation saved the keystrokes but removed the warning signs.

A dependable extraction workflow treats collection as an operating system, not a script. It records what each source returned, maps values through an owned schema, checks freshness and completeness, stops suspicious runs, and tells a named person what failed. The goal is not to move data automatically. It is to make the data usable and the failure visible.

Do you need an API, a data provider, a tool, or custom extraction?

Start with the maintained option that meets the requirement. Custom software becomes sensible only when the value of the missing workflow exceeds the cost and responsibility of owning it.

Choose by the source of the constraint

ScenarioRecommendationReason
A supported API, export, or licensed feed provides the required fieldsUse the maintained sourceA documented interface is usually more stable and cheaper to operate than collecting the same data through a user interface.
A few predictable sources feed a spreadsheet or database with low consequenceConfigure a self-serve extraction toolA maintained product may cover scheduling and simple mapping without creating custom software to own.
Several changing sources must become one proprietary, validated data modelBuild a controlled extraction workflowCustom logic can own source adapters, normalisation, provenance, entity resolution, delivery, and failure recovery as one system.
Nobody owns field definitions, source priority, access rights, or acceptable stalenessRepair the data contract firstAutomation cannot make an undefined or unauthorised source trustworthy. Clarify the record and decision before collecting more data.

Use intelligent document processing when PDFs, scans, forms, or attachments must become checked business records. Use OCR development when recognising text from images is the main missing capability. This page is for collection and normalisation across sources that behave differently and change over time.

Production scope

What must work from source to accepted record?

The extractor is only one replaceable part. The durable product is the data contract, operating evidence, and recovery path around it.

  • 01
    Source access and collection boundaries
    Inventory each website, portal, API, export, inbox, database, or file drop. Record the approved access method, account ownership, rate and schedule limits, data rights, retention constraints, and what the workflow must never collect. Use the most stable maintained interface available.
  • 02
    Source adapters and raw evidence
    Collect through the appropriate interface, including APIs, downloads, browser flows, email events, SFTP, or database reads. Preserve permitted raw responses and source identifiers long enough to diagnose a disputed value, missing page, unexpected empty run, or source change.
  • 03
    Canonical schema and provenance
    Map different names, formats, currencies, units, categories, dates, and nested structures into one versioned schema. Attach source, collection time, transformation version, and other required lineage so an important value can be traced without reconstructing the whole run.
  • 04
    Validation, deduplication, and entity resolution
    Check required fields, types, formats, ranges, cross-field rules, reference records, and source totals. Separate exact duplicates, likely duplicates, updates, and genuine separate entities. Conflicting values follow an approved source priority or stop for review.
  • 05
    Scheduling, change detection, and backfill
    Run at the frequency the business needs, with idempotent checkpoints, retries, rate-limit handling, and restartable historical batches. Detect selector, schema, volume, distribution, and freshness changes before an apparently successful job contaminates downstream data.
  • 06
    Delivery, monitoring, and reconciliation
    Deliver accepted records to a database, warehouse, API, product, spreadsheet, or queue in the target contract. Record what the destination accepted or rejected, expose stale and failed runs, alert a named owner, and keep a documented recovery and replay path.
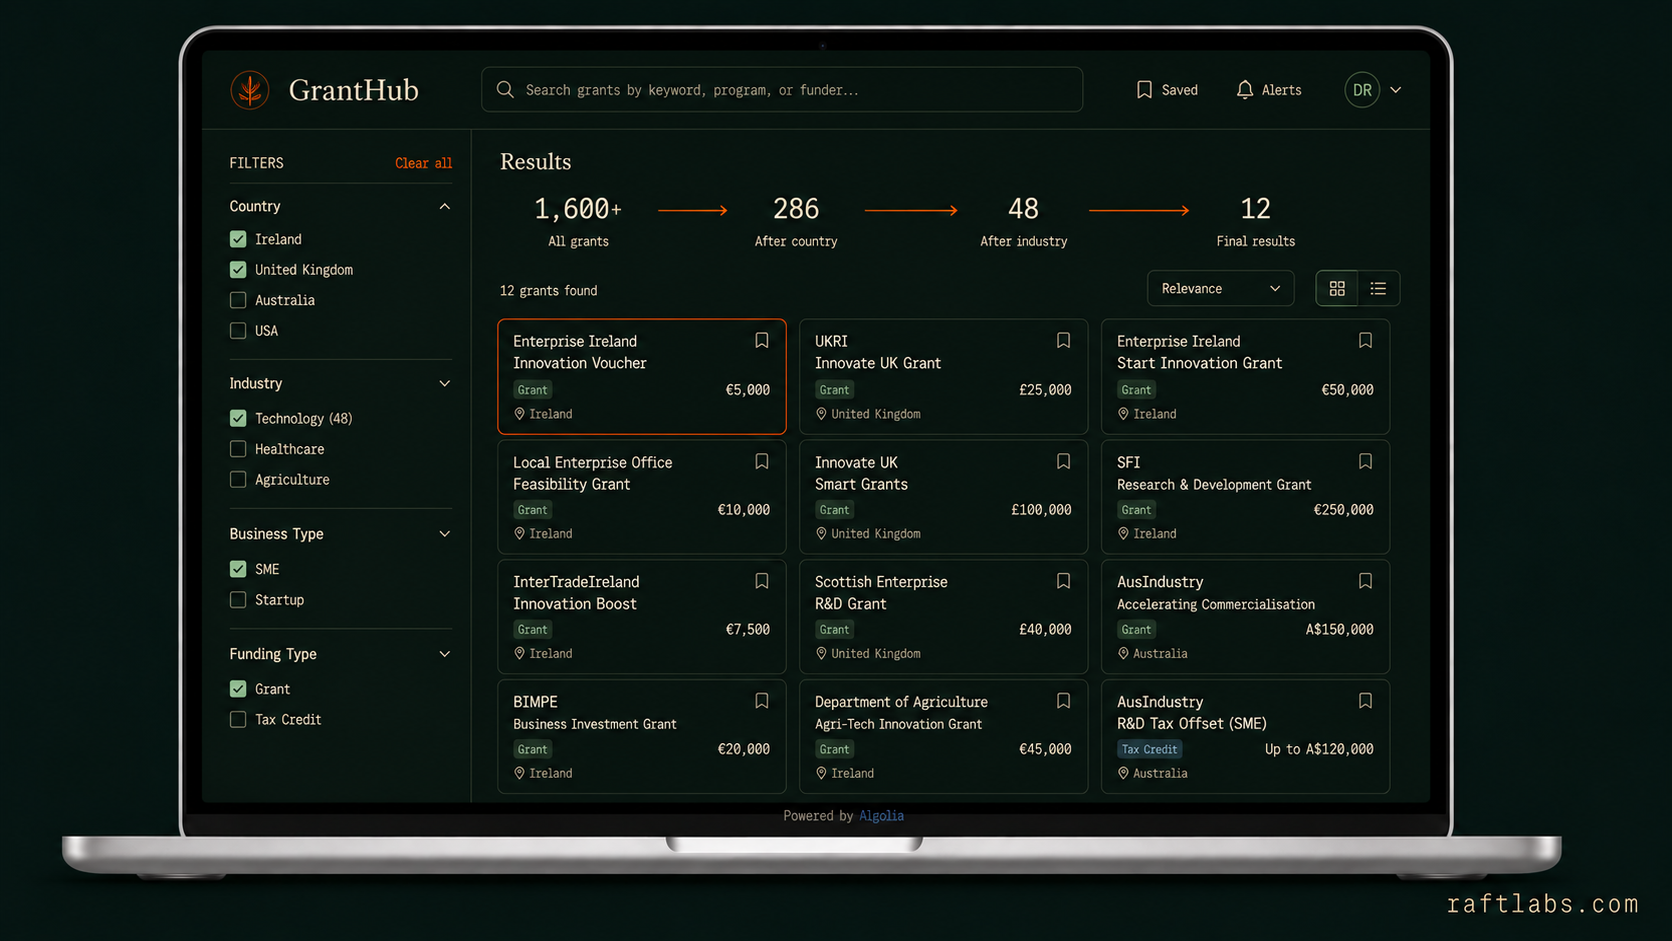
GrantHub filtering a structured grants catalogue by country and industry
GrantHub turns differently structured funding programmes into one filterable catalogue. The case study records 1,600+ active listings across 21 countries.

Recorded proof

GrantHub needed one useful schema across sources that described funding differently.

Government sources across 21 countries did not use the same terminology or structure for funding amount, eligibility, deadline, industry, and business type. A search product could not compare those programmes until the information was normalised into fields that meant the same thing across the catalogue.

RaftLabs built GrantHub, a searchable directory with more than 1,600 active grants, tax credits, and funding programmes. Automated checks against official feeds help detect changes, while a manual review cycle handles discrepancies and keeps source interpretation accountable. Scheduled AWS Lambda work syncs the structured catalogue to search.

That case proves multi-source normalisation, scheduled checks, review, and delivery into a user-facing product. It does not prove that every government portal was scraped automatically, that arbitrary sources can be accessed reliably, or that another extraction workflow will inherit the same 12-week product timeline.
What should a data owner measure before trusting the feed?

A run can finish successfully and still produce incomplete, stale, duplicated, or wrongly mapped data. Measure the business contract, not only the job status.

  • 01
    Source coverage and freshness

    Record which sources ran, the latest successful collection time, expected and actual record ranges, pages or partitions covered, and records delayed beyond the agreed freshness window. A recent timestamp does not prove the complete source was collected.

  • 02
    Field completeness and validity

    Track required-field presence, parsing and type failures, values outside approved ranges, cross-field inconsistencies, reference-data misses, and quality by source. Different fields carry different consequences and should not disappear inside one percentage.

  • 03
    Source and schema change detection

    Detect missing selectors, renamed or removed fields, unexpected nesting, changed labels, unusual distributions, empty results, and new categories. Preserve enough evidence to compare the suspicious run with a known source example.

  • 04
    Duplicate and entity-resolution outcomes

    Count exact duplicates, likely matches, updates, conflicts, manual decisions, and later corrections. A deduplication rate is incomplete without false merges and missed duplicates, because both distort the downstream record in different ways.

  • 05
    Destination reconciliation and operating cost

    Track accepted and rejected deliveries, retries, partial writes, replay outcomes, provider and infrastructure cost, manual review time, and incidents by source. Collection is not complete until the destination contains the intended record once.

How it works

Close one source risk before opening the next.

Each phase produces an inspectable decision. More sources and fields enter only after the current feed can be explained, operated, and recovered.

  1. 01
    Frame

    Define the source and data contract

    Which records are useful, where may they come from, and what makes them acceptable?

    Trace one record from source to business use. Separate what the source states from what the business infers, then define required fields, stable identifiers, expected volume, collection frequency, retention, and the conditions that must stop a run.

    Decision produced

    An authorised source inventory, target schema, provenance and freshness rules, validation and source-priority policy, destination contract, and named costly failures.

    Risk closed

    Automating collection while field meaning, access rights, record identity, and acceptable staleness remain implicit.
  2. 02
    Compare

    Compare maintained options and test access

    Can an API, export, provider, or product meet the requirement with less ownership?

    Test representative sources and known awkward cases. Confirm authentication, pagination, rate limits, historical access, sample values, and contractual restrictions before a production architecture is approved.

    Decision produced

    A comparison of available interfaces, coverage, freshness, rights, authentication, stability, cost, destination fit, and maintenance burden, with a buy, integrate, build, narrow, or stop recommendation.

    Risk closed

    Commissioning a scraper where a supported feed exists, or choosing a cheap source that cannot lawfully or reliably supply the required record.
  3. 03
    Control

    Build one controlled feed

    What is the smallest source-to-destination path that removes useful work?

    Build the ordinary path and the known failures together. Make stale, empty, duplicated, conflicting, and rejected data visible. Keep the current process available while the new feed proves its coverage and recovery behaviour.

    Decision produced

    One source cohort, versioned schema, extraction adapter, raw evidence boundary, validation and entity rules, delivery contract, monitoring, and replayable acceptance tests.

    Risk closed

    Adding every source before the team can diagnose a missing record, conflicting value, schema change, or rejected destination write.
  4. 04
    Operate

    Operate, recover, and expand by evidence

    Does the live feed stay useful when sources, credentials, and data distributions change?

    Assign a source owner and runbook, rehearse a failed collection and replay, and add confirmed failures to regression tests. Add another source only after its differences are understood and the first operating boundary remains dependable.

    Decision produced

    A monitored release with freshness, coverage, field quality, entity outcomes, destination reconciliation, incidents, recovery time, cost, and rollback evidence.

    Risk closed

    Expanding a pipeline whose successful job status hides missing pages, stale values, or repeated manual repair.

What should remain under client control?

These conditions belong in the scope, acceptance criteria, and handover. They should not depend on a general promise that the extractor is reliable or compliant.

  • 01
    Source authority and acceptable use

    The client confirms the authority to access, collect, store, transform, and reuse each source for the intended purpose. Terms, privacy, licence, contractual, and sector-specific questions are raised before implementation, with legal review where needed.

  • 02
    Schema and source-priority decisions

    Named business owners approve field definitions, identifiers, transformations, allowed values, freshness, duplicate behaviour, and what happens when sources disagree. The code should implement those decisions, not invent them quietly.

  • 03
    Credentials, data, and retention

    Client-controlled accounts are preferred. The scope records where credentials, raw responses, transformed data, logs, and failure evidence live; who can access them; how long they remain; and which third-party terms apply.

  • 04
    Lineage, failure evidence, and recovery

    Operators can identify the source, run, transformation, validation, and destination outcome for an important record. Alerts have an owner, and a documented manual or replay path remains available when collection or delivery fails.

  • 05
    Code, tests, and operating knowledge

    Project-specific code, schemas, transformations, evaluation examples, monitoring definitions, runbooks, and client accounts remain under client control, subject to stated source and third-party licence terms.

Every data extraction project starts at $9,500.

The first paid phase closes one expensive uncertainty before a larger production commitment is made.

If an API, export, licensed provider, or maintained tool meets the requirement with less cost and ownership, the recommendation should be to use it. Custom development begins only where the tested options leave a valuable gap.

What the first phase can be

  1. 01

    Source and feasibility audit

    Inventory access, rights, authentication, source variation, frequency, historical coverage, failure modes, and the maintained interfaces already available.

  2. 02

    Schema and data-quality map

    Define the required record, provenance, source priority, identity, transformations, validation, freshness, and acceptance evidence before choosing the extraction method.

  3. 03

    Provider and tool benchmark

    Test suitable APIs, licensed datasets, extraction products, and custom approaches on representative sources and known failures, then state the smallest sensible option.

  4. 04

    Controlled extraction proof

    Prove one authorised source-to-destination path with versioned mapping, validation, change detection, visible failures, and a replayable recovery path.

The first phase may be one of these or a deliberately smaller combination. Production scope is priced after source access, data variation, and operating responsibility are visible.

Starting investment

Starts at $9,500

Start with one source cohort, one useful schema, one destination, and the evidence needed to choose the next step.

Price held for the phase

The agreed phase price does not move unless you approve a material change in scope. New sources, fields, destinations, schedules, or historical backfills wait for a separate decision.

Source and failure boundaries written down

The scope states which sources and records are included, how they may be accessed, what can pass automatically, what must stop, and which evidence is required before release.

Client-controlled assets

Project-specific code, schemas, data, evaluation examples, client accounts, and operating notes remain under client control, subject to stated source and third-party licence terms.

Data extraction automation questions buyers ask

Data extraction automation collects selected information from a website, portal, API, email, file, database, or legacy interface without a person repeatedly copying it. A complete workflow also maps the result to a defined schema, validates important fields, resolves or flags duplicates, records the source and collection time, delivers accepted data, and makes failed or stale runs visible.

Data extraction automation is the broader multi-source problem. Its inputs can include websites, logged-in portals, APIs, spreadsheets, emails, databases, and documents. Intelligent document processing is specifically concerned with turning PDFs, scans, images, forms, and attachments into validated records, usually with classification, field extraction, human review, and write-back.

Web scraping is one collection method. Data extraction automation includes the operating workflow around collection: permitted access, schedules, source identity, schema mapping, validation, deduplication, change detection, delivery, reconciliation, and recovery. If an API, export, or licensed feed is available and suitable, scraping may be unnecessary.

Use a maintained tool or provider when it supports the required sources, fields, frequency, data rights, authentication, scale, and destination at an acceptable cost. Consider custom development when several sources must map to a proprietary schema, unusual validation or entity resolution is essential, a product leaves substantial repair work, or the extraction must sit inside an existing product. The first phase should compare the real options rather than assume a build.

Possible sources include public websites, authenticated partner or government portals, REST or GraphQL APIs, CSV and spreadsheet exports, XML or EDI feeds, SFTP drops, email bodies and attachments, relational databases, and supported legacy interfaces. Feasibility depends on authorised access, source stability, rate limits, terms, data rights, authentication, field complexity, and the consequence of a missing or incorrect record.

The workflow should detect more than a crashed job. It can monitor record counts, missing required fields, schema changes, selector failures, unusual value distributions, stale timestamps, and differences from known source examples. A failed or suspicious run should stop or quarantine affected records, alert an owner, preserve diagnostic evidence, and support a controlled replay after repair.

It depends on the source, access method, contract, jurisdiction, information collected, and intended use. Public visibility does not automatically settle terms of service, copyright, privacy, database rights, or sector-specific obligations. The scope should record the client's authority to access and use the data. RaftLabs does not promise to bypass access controls or provide legal advice; legal review belongs with qualified counsel where the risk warrants it.

Usually, yes, when the API exposes the required data with acceptable coverage, freshness, stability, licence terms, and cost. The comparison should include official APIs, bulk exports, notifications, licensed providers, and direct integrations. A browser-based extractor should not replace a maintained source interface without a clear reason.

Quality is defined field by field and source by source. Checks can cover required values, type and format, allowed ranges, cross-field relationships, source totals, reference records, duplicate identity, freshness, and reconciliation with the destination. The team should also track false acceptance, missing records, corrections, and the share of data held for review rather than publish one broad accuracy percentage.

Each accepted record can retain the source system or URL, collection time, source identifier, raw response or permitted snapshot, extractor version, transformations, validation results, and destination identifier. The exact evidence retained depends on data rights, storage cost, privacy, and audit needs. A person should be able to explain where an important value came from and which logic changed it.

The scope defines stable identifiers where they exist and a deterministic matching policy where they do not. Exact duplicates, likely duplicates, updates, and genuine separate entities need different outcomes. When sources disagree, the workflow should apply an approved source priority or send the conflict to review rather than quietly keep the latest value.

Yes, when the source permits it and historical records remain available. Backfill and recurring collection should be scoped separately because pagination, historical format changes, rate limits, duplicates, and cost differ from an incremental run. A backfill should be restartable and reconciled in batches so one failure does not require starting again.

Useful monitoring covers whether each source ran, how many records were seen, accepted, changed, rejected, or delayed, how fresh the latest successful data is, which validations failed, what reached the destination, and what the run cost. Alerts need a named owner and a recovery procedure. A green job status is not enough if the source returned an empty or incomplete result.

Credentials should use client-controlled accounts where practical and be stored in an appropriate secrets system rather than code or shared documents. The scope identifies what raw and transformed data is retained, who can access it, where it is processed, how long it remains, and which third-party terms apply. Encryption, role-based access, redaction, regional hosting, audit logs, and deletion controls can be included where required.

Project-specific code, schemas, transformation rules, evaluation examples, runbooks, and data remain under client control, subject to the licence and access terms of external sources, libraries, and providers. Client-controlled source and hosting accounts are preferred so access and operating history do not depend on RaftLabs.

Every RaftLabs project starts at $9,500. The first phase may cover a source and rights inventory, schema and data-quality contract, provider or tool benchmark, technical feasibility test, or one controlled source-to-destination proof. Production scope is priced after access, variation, run frequency, validation, monitoring, and destination constraints are understood.

A feasibility or decision phase can take a few weeks. A production feed takes longer and depends on source access, source count, data volume, schema complexity, authentication, validation, entity matching, run frequency, monitoring, historical backfill, and destination integration. The schedule is set after representative sources and acceptance criteria expose the real operating boundary.

Work with us

Bring the source your team no longer trusts.

In a 30-minute call, we will identify the source, the destination, the costly failure, and whether the sensible next move is to use an API, buy, integrate, build, narrow, or wait.

  • The first scope names authorised sources, required fields, freshness, provenance, validation, and the destination contract.
  • APIs, exports, licensed providers, and maintained tools are compared before custom extraction is recommended.
  • Every failed, stale, duplicate, conflicting, or rejected record gets a visible owner and recovery path.
  • Project-specific code, schemas, evaluation examples, client accounts, and operating notes remain under client control.