AI for Fintech Development
AI for fintech with controls around every consequential decision.
Fintech AI is not a shortcut around underwriting, fraud, AML, servicing, or operations policy. We build bounded capabilities for document review, investigation support, customer operations, and decision assistance with representative evaluation, human authority, traceability, monitoring, and reconciliation designed around the consequence of failure.
Bring the problem, the current workflow, or the existing code. We reply with a practical next step within one business day.
The brief
Start with what is not working.
Good software decisions begin with the constraint, not a list of features or a preferred technology.
Are analysts re-keying financial documents or assembling evidence across systems before they can make a policy-owned decision?
Is an AI initiative moving ahead without a shared view of prohibited actions, protected data, reviewer authority, drift, appeals, or reconciliation?
Plain answer
AI for fintech applies models to bounded financial workflows such as document review, investigation support, servicing, and decision assistance. RaftLabs builds the surrounding controls: representative evaluation, data boundaries, deterministic policy checks, human authority, traceability, monitoring, reconciliation, and recovery. A focused first system starts at $40K and typically takes eight to twelve weeks after access and scope are approved.
A faster decision is not better if nobody can reconstruct it.
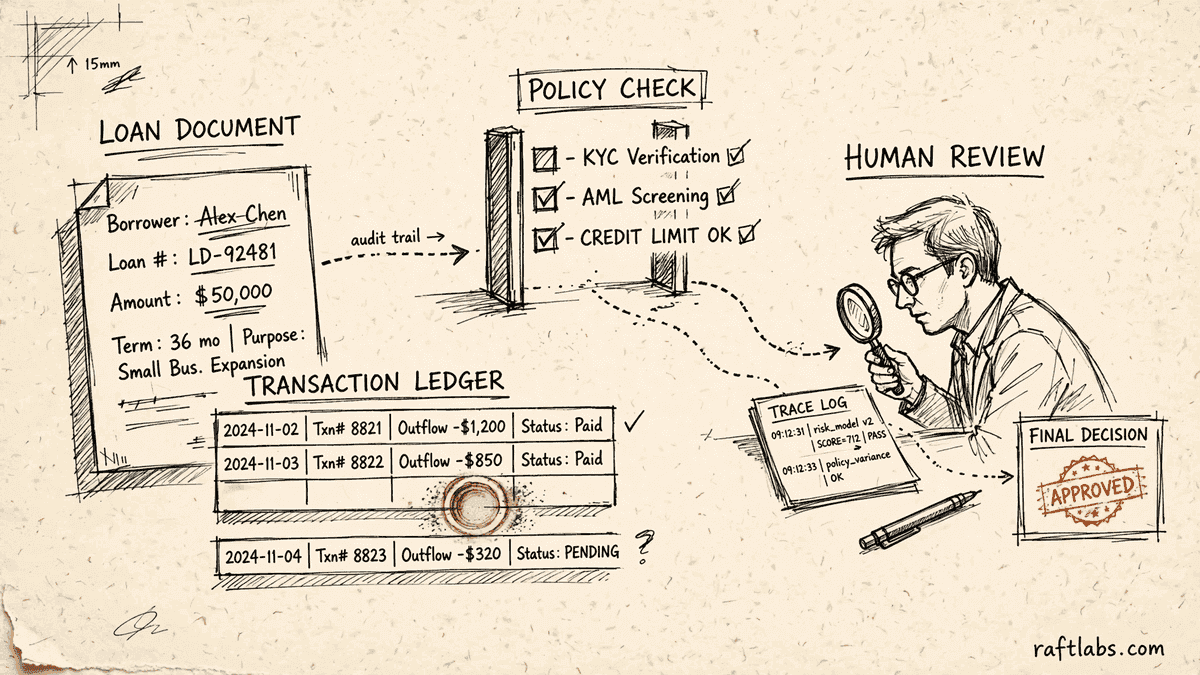
An operations team wanted AI to reduce a document queue. The first proposal connected extraction directly to a customer decision. Mapping the consequence changed the design: AI prepared the evidence, deterministic code checked policy, an authorised reviewer made the consequential call, and the system recorded the path from source document to outcome.
The boundary around the model mattered more than its fluency.
Recorded fintech delivery and commercial scope
- 10K+
- transactions in three months
- Recorded mobile POS launch
- PCI DSS
- audit recorded as passed
- Customer project record
- $40K+
- focused AI system start
- One bounded use case
The mobile point-of-sale case study records more than 10K transactions in its first three months and states that the platform passed a 2025 PCI DSS audit. It is evidence of payments engineering and operational delivery, not proof of an AI credit, fraud, or AML model. Figures and audit status come from retained project records and are not independently audited by RaftLabs.
Start with a reviewable use case and an accountable policy owner.
The first release should reduce operational work without silently transferring business or regulatory authority to a model.
The workflow has a clear baseline, representative cases, lawful data access, and people authorised to judge outcomes.
AI can prepare evidence, flag cases, or assist a decision inside a defined policy and human-review path.
Product, engineering, security, risk, operations, and compliance owners can participate in scope and acceptance.
The goal is to deploy autonomous credit, fraud, AML, or trading decisions without qualified review and policy approval.
Historical outcomes are unavailable, poorly defined, or known to encode unacceptable decision practices with no remediation plan.
The organisation expects software delivery to replace legal interpretation, model-risk ownership, or regulatory approval.
Where AI can sit in a fintech decision
| Role | Assistive AI | Rules and policy engine | Automated model decision |
|---|---|---|---|
| Typical work | Extract, retrieve, summarise, match, or draft | Enforce approved deterministic policy | Score or decide within an approved boundary |
| Human authority | Reviewer accepts or corrects | Policy owner approves rules and exceptions | Varies by consequence, policy, and applicable obligations |
| Evidence | Sources, citations, correction, and reviewer action | Rule version, inputs, outcome, and override | Dataset lineage, validation, monitoring, reason or explanation, appeal, and outcome review |
| First-release fit | Often the safest starting point | Essential around model-assisted actions | Only with mature data, governance, validation, and approval |
Scope
What a controlled fintech AI system includes
- 01
Use-case and policy boundary
Name the affected user, current process, decision owner, applicable internal policy, automated and prohibited operations, human-review authority, appeal or correction path, and measurable baseline. - 02
Data and evaluation design
Trace source, rights, lineage, representativeness, missingness, temporal change, protected or sensitive attributes, labels, segment performance, leakage, and the holdout used for acceptance. - 03
Model-assisted workflow
Build only the required extraction, classification, matching, retrieval, summarisation, or scoring component. Surround it with deterministic validation, permissions, case state, and dependable integrations. - 04
Reviewer and audit experience
Present evidence, uncertainty, relevant checks, and correction controls to the authorised reviewer. Record model, input, rule, reviewer, override, and outcome without exposing unnecessary sensitive data. - 05
Monitoring and reconciliation
Observe quality, drift, latency, cost, review load, subgroup outcomes where appropriate, API health, record mismatches, complaints, overrides, and incidents. Provide quarantine, rollback, replay, and change records.
How it works
From regulated use case to controlled release
- Phase 101
Select the regulated use case
Define the customer or operator outcome, current policy, decision owner, prohibited operations, baseline, evidence, jurisdiction, and release boundary.
- Phase 202
Map data controls and harm
Trace data rights, sensitivity, lineage, affected groups, access, retention, vendor exposure, review authority, appeal, and failure consequences.
- Phase 303
Build and validate safely
Implement the bounded capability, enforce deterministic policy and permissions, evaluate representative cases, and test security, integration, reconciliation, and recovery.
- Phase 404
Launch with monitoring
Release by cohort or queue, observe quality and drift, review outcomes, reconcile records, document changes, and transfer operating and incident runbooks.
Risk
Questions that must be answered before release
- Decision authority
- State whether AI prepares evidence, recommends, routes, or decides; who can override it; and which outcomes always require authorised human approval.
- Data and model change
- Record data lineage, training or configuration changes, evaluation versions, vendor updates, drift thresholds, retraining authority, and the conditions that pause automated use.
- Customer recourse
- Design correction, appeal, complaint, and investigation paths appropriate to the use case. A human-review badge is not enough if the reviewer lacks evidence or authority.
- System reconciliation
- Reconcile model events with ledgers, case systems, communications, and downstream actions so retries or partial failures cannot silently change a financial record twice.
Scope and price
A focused fintech AI system starts at $40K.
Start with one bounded workflow, representative cases, approved policy, model-assisted capability, deterministic controls, core integration, review experience, and monitored release.
The proposal separates software engineering from the customer's legal, compliance, model-risk, and policy responsibilities.
Starting investment
Starts at $40K
A focused first system typically takes eight to twelve weeks. Data remediation, specialist labels, multiple cores, high availability, formal assurance, or multi-jurisdiction review can extend scope.
Consequential authority is explicit
Evidence travels with the outcome
Related fintech and AI delivery paths
- 01
Fintech Software Development
Build full lending, payments, banking, or financial operations products and integrations.
- 02
AI Workflow Automation
Automate a bounded operational path with interpretation, review, audit, and recovery.
- 03
Intelligent Document Processing
Extract and validate data from statements, forms, invoices, IDs, and supporting documents.
- 04
AI Consulting
Rank AI use cases and define the investment, governance, and evaluation roadmap before a build.
Work with us
Bring one fintech workflow and the consequence of getting it wrong.
Share the policy owner, representative cases, data boundary, current baseline, human-review path, prohibited outcomes, integration surface, and launch jurisdiction. We will scope a controlled first release.
- Scope and cost agreed before work starts. No surprises. No obligation.
- Working prototype within 3 weeks of kickoff.
- Pay by milestone. You see progress before each invoice.
- 60-day post-launch warranty. Bug fixes, UI tweaks, and deployment support. No retainer.
- All conversations are NDA-protected.
Frequently asked questions
Straight answers to what buyers ask before they scope. Still stuck? .
Document classification and extraction, investigation summarisation, customer-service assistance, evidence retrieval, record matching, and draft generation can be suitable when outputs are reviewable and the workflow has clear owners. Automated credit, fraud, AML, or customer-impacting decisions need stricter evidence, authority, appeal, monitoring, and legal review.
We can assess and build bounded analytical or workflow components when the customer supplies lawful data, policy owners, labels, evaluation criteria, and qualified risk and compliance involvement. We do not promise approval rates, fraud reduction, AML compliance, or regulatory acceptance. A production decision system requires scope beyond a model endpoint.
The design records source evidence, model version, relevant inputs, deterministic checks, confidence or reason codes where appropriate, reviewer action, and the final system outcome. Human review is assigned by consequence and policy. Your authorised risk, compliance, and legal owners decide what explanation and approval standard applies.
No. We provide product and software engineering. Your legal, compliance, security, model-risk, and business owners interpret applicable rules, approve policy, validate required controls, and decide whether a use case can launch. We implement agreed technical controls and evidence but do not certify that a system satisfies every obligation.
A focused first system starts at $40K and typically takes eight to twelve weeks after data, access, and decision policy are ready. Historical-data preparation, specialist labels, several core integrations, high availability, independent testing, formal model validation, or multi-jurisdiction evidence can increase scope and duration. The written quote names the capability being built, the systems it connects to, the evaluation and human-review work, and the outcome it is measured against. If the scope changes after that, the change is priced in writing and approved by you before the work happens.
Financial data security requires specific architectural decisions. We use private LLM deployments (Azure OpenAI, AWS Bedrock, Anthropic Claude on private infrastructure) with data processing agreements that prohibit training on your data, rather than sending sensitive financial data to public APIs. For data that can be processed via public API under an appropriate data processing agreement, we apply data minimisation (sending only the relevant excerpt, not the full document). All financial data is encrypted in transit and at rest. Access is role-controlled and audited. We confirm the appropriate architecture based on your specific data classification and regulatory requirements during scoping.
Accuracy depends on your document types. We run validation pipelines: LLM extraction, confidence scoring, a human review queue for low-confidence extractions, and accuracy reporting over time. For unstructured summarisation and analysis, accuracy is harder to measure precisely, which is why human review workflows are standard for any AI output used in a financial decision. We build in the measurement from day one so you can track and improve accuracy systematically.
Yes. Most financial AI projects we build connect to existing core banking systems, CRMs, document management platforms, or portfolio management systems via API. Common integrations include Salesforce, Temenos, Finastra, and custom-built policy or case management systems. We confirm integration feasibility and scope the connection points during discovery before any development starts. Integration complexity is a major cost driver, so this is a question we ask early.
Yes. We sign NDAs before any discovery conversation where financial document types, system architecture, or client data is discussed. For production systems handling actual financial data, we also sign data processing agreements and confirm the appropriate LLM deployment model (private cloud, API under a data processing agreement, or on-premise) before scoping begins. Client confidentiality is standard practice, not a negotiation.
You do, from day one. The code, the cloud and platform accounts, and the project notes are yours from the start of the project, not handed over at the end. The models run in accounts in your name, so usage and cost stay visible to you. Third-party models and services keep their own terms, and those are named in the scope document before you sign.
Nothing needs to be extracted from us. You already hold the code and the project notes, your platform, cloud, and model accounts are in your name, and the notes are kept current while the work runs. A new team starts from what you hold. There is no unlock fee and no final handover where the keys change hands, because they were never ours to keep.
No. The people who scope your system stay on it through delivery, and you can speak to them directly at any point. Our teams are in India & Ireland. There is no second team waiting to inherit your project after the contract is signed.
We work on five remote work principles. Switch to Async: most updates travel in writing you can read in your own hours, not in meetings called to report status. Be Prepared: calls happen when a decision needs them, with the material sent ahead. Write: decisions, scope changes, and open questions are written down where both sides can find them later. Ask/tell: we ask early when something is unclear and tell you early when something changes, including bad news. Own: a named person on our side owns each piece of work and its outcome. Progress is visible as a working system you can review, and in the evaluation and review records the build produces, not as a percentage in a report.
A focused first system typically takes eight to twelve weeks after data, access, and decision policy are ready. That calendar is not only building time. It includes your policy and risk owners reviewing evaluation results, access being approved to the systems the capability connects to, and reviewers confirming the cases the system must handle. A week spent waiting for access or for a review decision is a week on the calendar, which is why the scope names the owners and the review path before the build starts.
After launch, support runs as another fixed phase, an ongoing engagement, or your own team working from the handover notes. Whoever maintains it, the standing costs continue: model and API usage, hosting, monitoring, and updates when a model, a provider, or a connected system changes. We estimate those running costs in the scope document against your expected case volume, so they are visible before you sign, and model performance stays tracked against the outcome agreed at the start.
Yes, AI helps produce the work, and the risk you are really asking about is unchecked output quietly becoming part of a system that handles money and regulated decisions. That is why the work runs through RaftKit, our published method at raftkit.com. It has five phases: Blueprint, Plan, Build, Review, and Compound. Each phase has quality gates it must clear before the next one starts. Review happens in two stages: first a check that the work matches what was asked for, then a wider review by specialised reviewers from several angles. Findings are graded by severity, and a serious finding blocks the work from going out. AI speeds up production. The gates, the two reviews, and the block on serious findings are what make its output safe to build on.