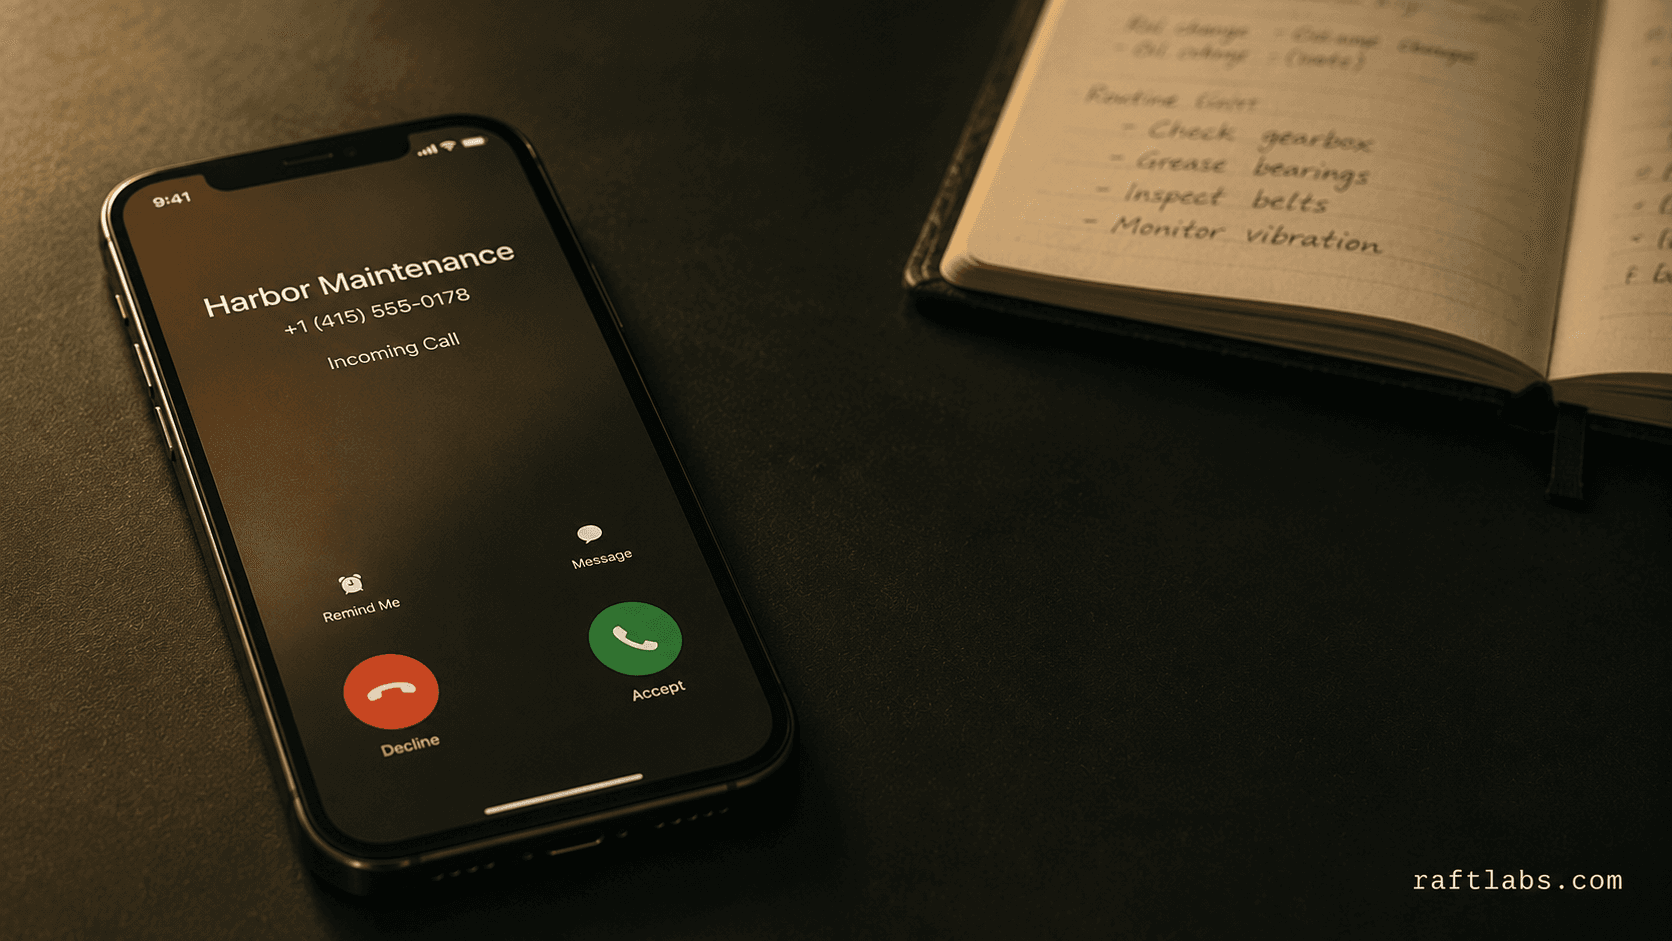
AI phone agents for adaptive voice interviews
A voice-first interview platform that calls respondents, adapts follow-up questions, retries missed calls, and prepares findings when the campaign ends.
AI Development Company
Bring one use case, an AI-built prototype, or a feature that already works on the happy path. We identify what the system must get right, test it on representative inputs, and build the software around the model so people can review failures, understand costs, and stay in control as usage grows.
Bring one workflow or prototype. Leave with a buy, integrate, test, build, or stop recommendation.
Trusted by



The brief
Good software decisions begin with the constraint, not a list of features or a preferred technology.
The demo looks convincing, but nobody can say what happens when the input is incomplete, ambiguous, or hostile.
People keep changing prompts because there is no agreed test for a good answer.
The model works, but permissions, integration, human review, and cost at real volume are still undefined.
Plain answer
AI development turns a business task into a working system that can be measured, reviewed, and operated. The work includes the user workflow, data, model or provider, integrations, evaluation set, permissions, human review, monitoring, and cost controls. Every RaftLabs project starts at $10,000.
What to remember
A model is not automatically the answer. We use five possible recommendations before discussing a larger development scope.
Use a maintained product when it handles the task, accepts the right data, meets the quality threshold, and gives the business enough control. A subscription is often better than owning another system.
Add an existing model or AI service to the product when the task is differentiated but the underlying capability is not. Own the workflow, evaluation, and customer experience without pretending to own the model.
Run a bounded test when data readiness, output quality, latency, cost, or reviewer effort is uncertain. The result should be a go, narrow, change, or stop decision, not a polished demonstration.
Develop the full system when AI quality, proprietary data, workflow control, or customer experience creates a real advantage. The scope includes the surrounding product and operating controls, not only a model call.
Do not automate a task that has no owner, no stable rule, no useful evidence, or no safe fallback. Removing an attractive but weak use case can be the most valuable outcome of the first conversation.
Not sure which path fits? Bring one use case to a 30-minute call: leave with the answer in writing.
Fit
The case becomes stronger when the task happens often, the current result can be measured, and a person can decide what the system may do when it is uncertain.
A user repeatedly reads, writes, classifies, predicts, searches, listens, or makes a decision that current software handles poorly.
Representative inputs and a current baseline exist for quality, time, cost, completion, or review effort.
A named owner can approve the output threshold, prohibited actions, human review, and first release boundary.
The goal is simply to add AI, with no changed customer or operating result attached.
The process itself changes every week and nobody is authorised to define the correct result.
The use case requires perfect open-ended output and has no safe refusal, review, or fallback path.
Not sure which side you are on? Bring the current workflow, not a feature list. The useful recommendation may still be to buy, integrate, narrow, or wait.
An AI problem usually begins where unstructured information slows a repeated decision. A person reads an email, PDF, image, transcript, or set of notes; extracts the useful parts; checks them against another system; applies judgement; and moves the work forward. The expensive part is often not reading. It is waiting, rechecking, and recovering when an unusual case appears.
Take an operations team that receives several document formats from customers. The visible request may be "use AI to extract the data." Extraction alone leaves most of the product unanswered. Which fields matter? What counts as correct? What happens when a page is missing? Which source should an operator see before approving a low-confidence result? Where does the accepted record go, and who can reverse it?
The right AI system reduces that whole path. It may extract the routine cases, show the source beside the result, send uncertain cases to a person, and write accepted data into the existing system. The useful measure is not how impressive the model sounds. It is how much work reaches the right outcome without hiding mistakes.
A prototype proves that an interaction is possible. A production scope defines what happens before, around, and after the model, especially when the answer is wrong.
You do not need to arrive knowing the technical category. Describe the input, the result, who uses it, and the cost of a wrong answer. Those facts point to the right approach.
Generative AI fits work where the output is language, an image, or another created response. When answers must come from company material, retrieval and citations matter as much as the model.
An AI agent fits when the system must choose and execute a sequence across tools. Give it the smallest permissions required, log each action, cap spend, and hand off when the path leaves its approved boundary.
Machine learning fits repeated decisions supported by historical examples, such as demand forecasting, prioritisation, or risk scoring. The scope includes the data pipeline, decision threshold, monitoring, and retraining path.
Document and computer-vision systems turn visual input into structured decisions. Confidence, field-level validation, duplicate detection, exception review, and delivery into a system of record complete the workflow.
Voice AI fits calls, interviews, and hands-free work. Real quality depends on latency, interruptions, accents, consent, call failure, escalation, and whether the conversation reaches a useful result.
Describe the job in plain language on a 30-minute call. We will point to the right approach. We will tell you if no AI approach is the honest answer.
Not always. The data requirement depends on the job and the approach. A language feature built on an existing model may need a representative set of requests and approved source material, not millions of training records. A document workflow needs the actual layouts, image quality, handwriting, missing pages, and field variations it will encounter. A prediction system needs enough trustworthy historical outcomes to test whether it improves on the current decision.
The more useful starting point is a small evidence pack: real examples, the result a knowledgeable person would accept, cases the system must reject or escalate, and a record of where the data came from. Someone close to the work must be able to explain why one answer is useful and another is wrong. That domain judgement cannot be recovered from a model catalogue.
If the source data is fragmented, sensitive, poorly labelled, or unavailable through the current systems, that does not automatically end the idea. It changes the first phase. We may need to prove access, establish a baseline, prepare a limited evaluation set, or recommend a non-AI workflow first. The point is to expose the constraint before a larger build depends on it.
Proof
Perceptional began with an idea for adaptive user interviews. Its founder describes the prototype, product decisions, and path into a working SaaS platform.
The case study records a 12-week concept-to-launch period and structured interview summaries available within 48 hours. It is one conversational AI project, not a promise that another use case will follow the same timeline or result.
Read the Perceptional case study"Accurate" is not one universal number. A receipt extractor can be checked field by field. A search assistant can be judged on whether it found the right source and stayed faithful to it. A forecast can be compared with the current method. An agent must be evaluated on the whole sequence of actions, including whether it used the right tool, asked for approval, and stopped when it should.
We begin with examples that reflect the work: common cases, rare but expensive cases, incomplete inputs, and outcomes the system must refuse. A domain owner writes or approves the expected result. Some checks can be automatic, while ambiguous answers need human scoring. A separate holdout prevents the team from tuning until it merely memorises the test.
The release threshold then becomes a business decision. A lower-confidence result may go to review instead of disappearing. A customer-facing answer may need a source. A high-impact action may always require approval. When the prompt, model, tool, or data source changes, the same evaluation runs again. That is how improvement becomes inspectable instead of a debate about which demo looked better.
How it works
Each stage answers a buyer question and leaves behind evidence. The next stage opens only when the uncertainty in the current one is understood well enough to accept.
Which user decision or task should change, and why is it worth changing?
Follow the work from input to outcome. Include the judgement, waiting, corrections, edge cases, and downstream system changes that a tidy automation brief usually leaves out.
Decision produced
Risk closed
Can the smallest credible approach clear the quality and economic threshold on real examples?
Test existing models and tools before reaching for custom training. Keep tuning examples separate from the final holdout, and include the cases that would be expensive or embarrassing to get wrong.
Decision produced
Risk closed
What must exist so a person can use, review, operate, and safely change the capability?
Make the important behaviour visible. A reviewer should know what the system saw, why a result needs attention, what action it took, and how to correct or reverse it where the workflow allows.
Decision produced
Risk closed
Does the live workflow improve the original baseline without creating an unacceptable new risk or cost?
Start with a controlled group or volume. Review corrections, refusals, escalations, latency, provider errors, and unit economics before increasing autonomy or adding another use case.
Decision produced
Risk closed
Ask every supplier to make these five conditions visible in the scope and operating plan. A model list or polished demonstration cannot answer them.
Task, evaluation set, scoring method, threshold, and owner are inspectable. "It looked right" is not acceptance.
What AI may decide, what it may only recommend, when it must refuse or escalate, and who can correct it.
Model calls, retrieval, compute, retries, and human review belong in the unit economics from the start.
Prompts, evaluations, settings, and connectors documented and versioned: a controlled migration path.
Repository, cloud, data, and model-provider access remain visible and client-controlled where practical.
Proof
A voice-first interview platform that calls respondents, adapts follow-up questions, retries missed calls, and prepares findings when the campaign ends.
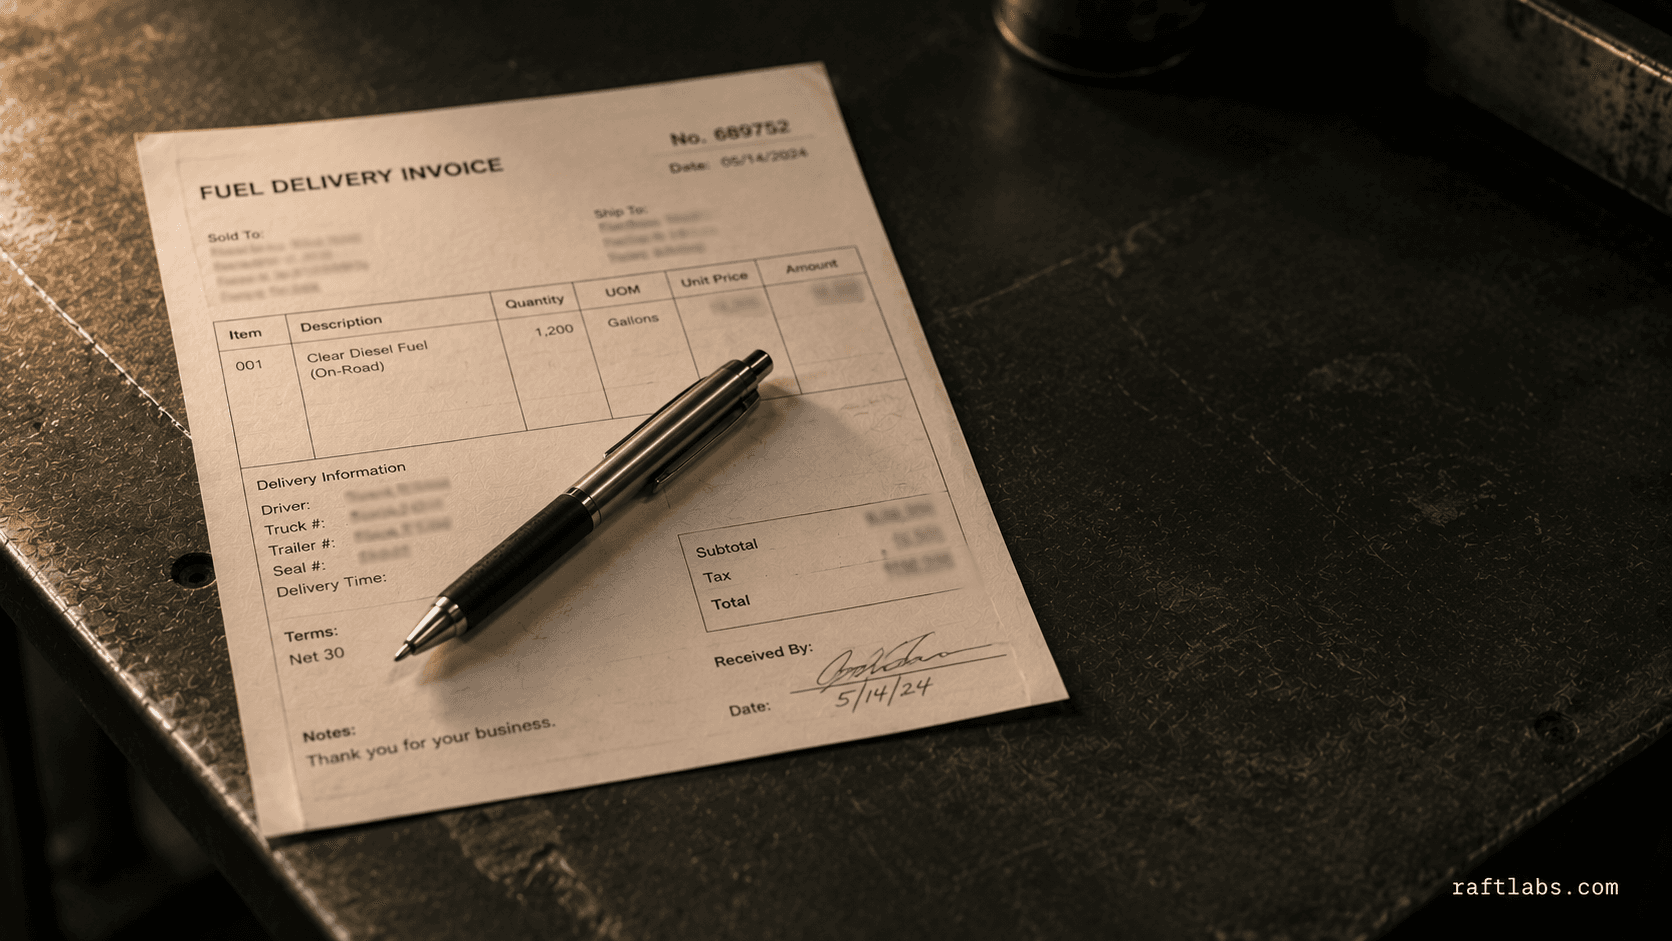
AI-based document processing connected invoice data with inventory, sales, and an existing point-of-sale system across a multi-location operation.
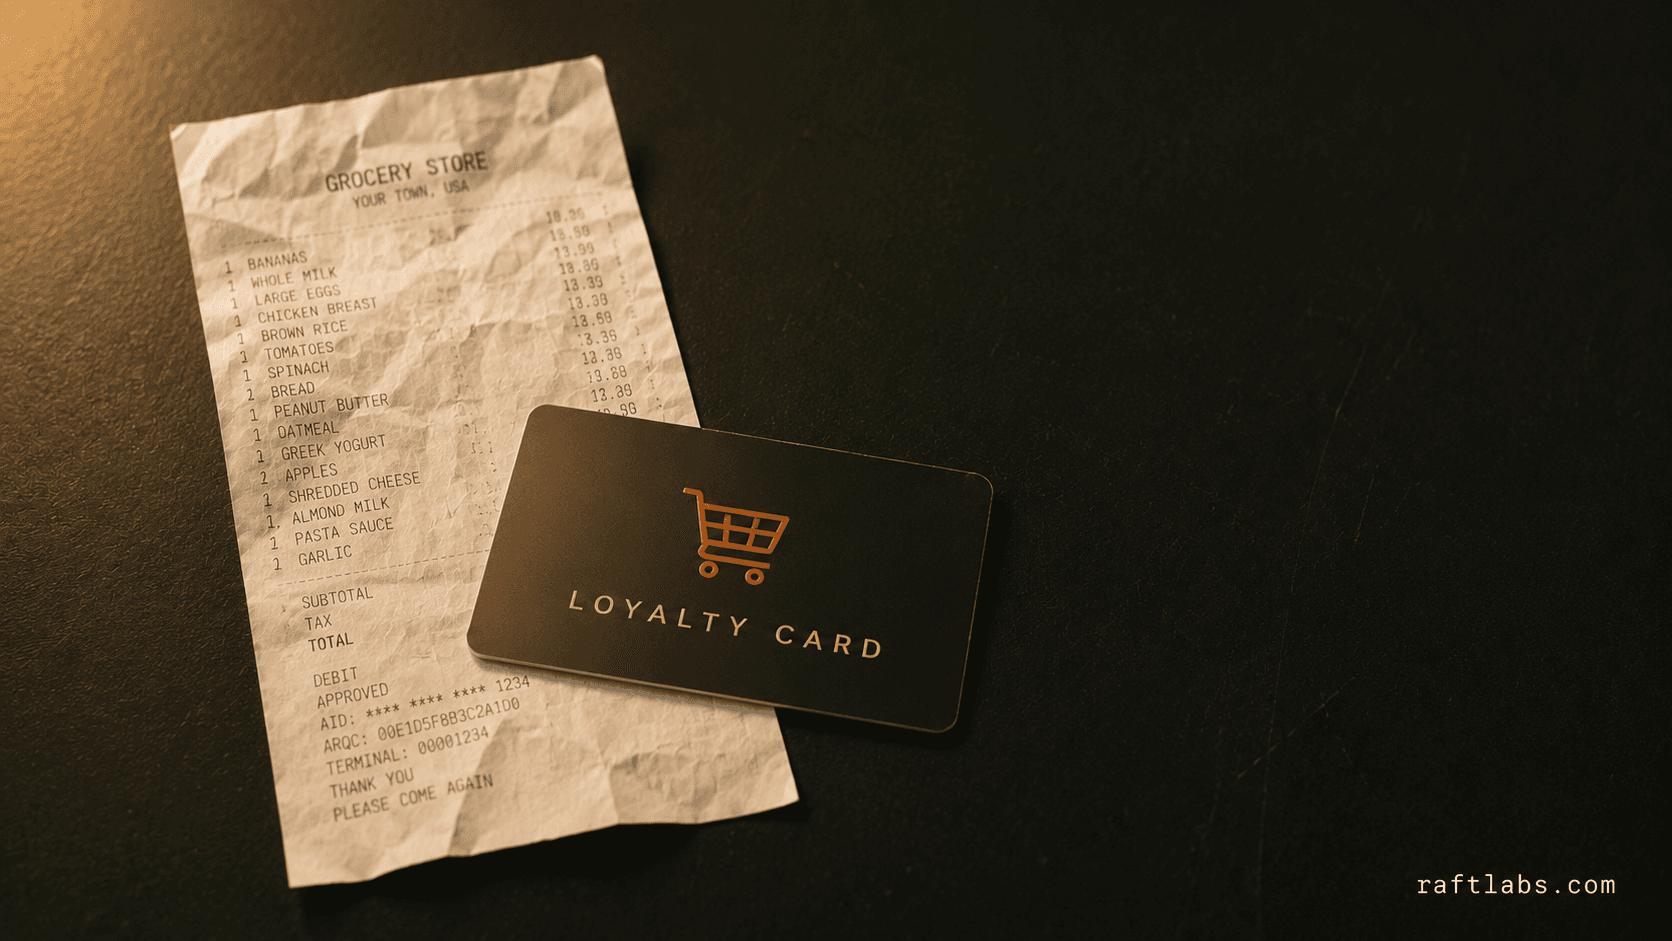
A receipt-validation platform turned customer uploads into campaign decisions, flagged duplicates and exceptions, and gave operators a review path.
The first paid phase is deliberately bounded. It may inspect an existing prototype, test one uncertain AI claim, define the production boundary, or deliver one controlled workflow.
The 30-minute buy, integrate, test, build, or stop session comes first and costs nothing. If there is a sensible paid next step, you receive the proposed evidence, scope, timing, and price. If there is not, the recommendation stops there.
Prototype or codebase audit
Identify what is safe to keep, where the current system fails, and what evidence is missing before real users or sensitive data depend on it.
Bounded feasibility proof
Test one uncertain claim on representative inputs with a baseline, threshold, failure analysis, latency, unit cost, and clear stop decision.
Production-readiness phase
Define the evaluation, permissions, source trace, review, fallback, monitoring, account ownership, and release boundary around an approach that already works.
One controlled AI workflow
Complete one useful path from input to outcome, including the interface, data, model, integrations, exception handling, and human authority it requires.
The evidence decides the first phase. Before it begins, you will know what question it should answer, what is included, what is excluded, and what would justify another phase.
Starting investment
$10,000
Minimum project scope. Price, acceptance criteria, ownership, and exclusions are written down before the phase starts.
A real stop decision
Price held for the phase
Client-controlled accounts
60-day launch warranty
Start from the outcome you need: an agent that acts, an assistant that answers, a workflow that runs itself, or AI tuned for your industry.
These are the useful next paths: rank several opportunities, test one selected use case, or inspect the costs and trade-offs before committing.
Use AI consulting when several ideas compete for budget and the business still needs a defensible build, buy, configure, or wait decision.
Use a proof of concept when the job is selected but quality, data readiness, latency, cost, or reviewer effort still needs evidence.
Check whether the use case, data, ownership, evaluation, workflow, and operating conditions are ready for a paid phase.
See how data, models, integrations, evaluation, security, volume, and operating support move the price of an AI system.
Work with us
In a 30-minute call, we will help you decide whether to buy, integrate, test, build, or stop. If AI is not the sensible answer, that is still a useful outcome.
AI development is the work of turning a defined business task into software that uses one or more AI models and can be measured, reviewed, and operated. An AI development company designs the interface, data flow, integrations, model or provider choice, evaluation, permissions, human review, monitoring, and operating-cost controls. Model access by itself is only one component.
Use generative AI when the system must create, rewrite, summarise, or answer from context. Use an AI agent when it must choose and execute several controlled actions. Use machine learning for prediction, ranking, or classification from historical data; document AI for PDFs, scans, and images; and voice AI when listening or speaking is part of the job. If the category is unclear, start with the workflow and the required result rather than selecting a technology first.
You do not always need a large, perfectly cleaned dataset. You do need representative examples of the real input, the expected result, awkward cases, prohibited outcomes, and permission to use the relevant data. A hosted language model may need examples and approved source material; retrieval needs accessible documents with useful structure; and predictive machine learning needs enough historical outcomes to test whether it beats the current method. If those conditions are unclear, the first phase should measure the gap instead of assuming the data is ready.
The recurring problems are an unclear task, no baseline for the current result, unrepresentative test examples, inaccessible or sensitive data, brittle integrations, no owner for low-confidence output, and operating costs that were never tested at real volume. Model quality can also change when a prompt, provider, tool, or source document changes. The first phase should expose the most expensive uncertainty and define who reviews, refuses, retries, corrects, and stops the system before a larger build depends on it.
Most first releases should begin with an existing hosted or open model and measure it against the real task. Fine-tuning can help when repeated domain patterns are not handled well by prompting or retrieval. Training a model from scratch is justified only when proprietary data, economics, control, or performance makes the additional cost and operating burden worthwhile. The evaluation should decide, not a preference for a particular vendor.
Start with a proof of concept when data readiness, output quality, latency, unit cost, or review effort is genuinely uncertain. A useful proof has representative inputs, a current baseline, a pass threshold, known prohibited outcomes, and a stop decision. If feasibility is already supported by credible evidence, scope the first production workflow instead of repeating discovery.
Do not use AI when a stable rule, ordinary automation, or maintained product can complete the job more reliably and cheaply. A useful test: if the decision repeats often, takes the same shape every time, and the answer already exists in your data or rules, encode the rule. Do not pay a model to guess it. AI is also a poor fit when the task is rare or low-value, nobody can define an acceptable result, the necessary data cannot be used, or a wrong answer has no safe review or fallback. In those cases, simplifying the process, improving the source data, buying a tool, or waiting can be the better recommendation.
Yes. The first step is to inspect the code, prompts, models, data flow, integrations, test coverage, provider accounts, security boundary, and current failure cases. Useful work stays. The parts that prevent measurement, safe change, or operation are replaced. An AI-built prototype can be a valuable specification and user test even when its production foundations need work.
Yes, if the current systems expose a safe way to read data or accept an action. Depending on the workflow, that may use an API, webhook, event stream, approved database view, file exchange, browser extension, or a small integration service. The scope identifies the source of truth, access permissions, retry and duplicate behaviour, human approval, and what happens when either the model or the connected system is unavailable. The goal is to improve the existing path without forcing the team to operate a disconnected AI tool.
The measure depends on the job: extraction may use field-level precision and recall, a retrieval system may measure source coverage and grounded answers, and an agent may be scored on the full sequence of actions. We build a representative evaluation set, separate tuning cases from holdout cases, define refusal and escalation behaviour, and rerun the same tests when prompts, models, tools, or source data change. No honest supplier can promise zero hallucinations for an open-ended generative system.
The scope identifies what data reaches each model provider, whether the provider may retain or train on it, where processing occurs, which users and systems can act, and what must be redacted, logged, reviewed, or prohibited. Client-owned accounts, least-privilege access, protected secrets, audit records, and human approval can be included where the workflow requires them. Your legal, privacy, security, and risk owners retain responsibility for interpreting applicable rules and approving release.
The useful answer depends on the first uncertainty, not a generic AI timeline. Auditing a prototype, testing one feasibility claim, and delivering a controlled workflow are different scopes. Data access, representative examples, integrations, user roles, review rules, security approval, and the number of release surfaces usually affect timing more than the model API itself. Before a paid phase starts, the deliverable, acceptance criteria, dependencies, exclusions, and phase timing are written down.
Every RaftLabs project starts at $10,000. The first phase may be a prototype or codebase audit, a bounded feasibility proof, a production-readiness phase, or one controlled workflow. The final price depends on data condition, evaluation depth, model and infrastructure choices, integrations, user roles, security requirements, expected volume, and the cost of failure. Scope, acceptance criteria, exclusions, and price are written down before the phase starts.
Ongoing cost can include model or inference usage, retrieval and storage, cloud compute, observability, provider fallbacks, retries, human review, support, and later evaluation or retraining. We estimate these against expected volume and track cost per useful result, not only cost per model call. Usage caps, routing rules, smaller models, caching, review thresholds, and client-controlled provider accounts can keep the economics visible as adoption changes.
Start with the current cost of completing the job, including staff time, waiting, rework, missed work, and the cost of errors. After release, compare completion rate, cycle time, review effort, accepted output, correction rate, and total operating cost against that baseline. The useful measure is cost or value per completed result, not the number of model calls. If the system moves work faster but creates more review or recovery elsewhere, that cost belongs in the calculation.
Every AI shop shows a similar demo, so ask what happens after it. Ask each company to show how it will decide whether to buy, integrate, or build; what representative data it will test, including the awkward cases; how quality and the cost of a wrong result will be measured; what happens when the model is uncertain or unavailable; and who controls the code, data, infrastructure, and provider accounts. Relevant production case studies with adoption data matter more than a model-logo list. Be cautious of pricing before a data review, a portfolio of pilots that never reached production, or vague answers on IP. A credible team should also be able to recommend a smaller automation, an existing product, or no AI when that is the better decision.
Brief on outcomes, not technology: the job to be done, what a good result looks like, what a wrong result costs, and who reviews it. Anyone who quotes confidently before asking deep questions about your workflow and data is guessing. Judge the work the same way: agree a small set of representative examples up front, including the difficult ones, and require the supplier to show measured results against them, not a live demo. Our process is built for this: every phase ends with a written recommendation and measured evidence you can read without technical background.
The client owns the project-specific application code, prompts, evaluation assets, and agreed project IP, and controls the repository, data, cloud, analytics, and model-provider accounts where practical. Third-party models and open-source components retain their own licence and service terms. Usage should be visible in client-controlled accounts so model cost and vendor exposure do not become a handover surprise.
The launch begins with a controlled user group or workload. Quality, refusals, escalations, latency, cost per completed task, provider errors, and user corrections are reviewed against the original baseline. Every launch includes a 60-day warranty for defects in the agreed scope, release support, and small interface corrections. Later improvement or model changes can continue as another fixed phase or ongoing product work.